
 Hadoop Big Data Analytics Solution Market | 2026-2036
Hadoop Big Data Analytics Solution Market Size, Share, and Industry Trends Forecast 2026-2036
Hadoop Big Data Analytics Solution Market Insights
North American cloud infrastructure capacity is consolidating as hyperscalers expand distributed data center footprints to support enterprise Hadoop workloads. Amazon Web Services leverages its managed EMR platform to dominate cloud-native deployments, while Microsoft sustains competitive pressure through Azure HDInsight integrations with enterprise productivity stacks. Cloudera anchors the on-premises segment with its hybrid data platform, offering unified governance across edge and cloud environments.
Hadoop Big Data Analytics Solutions comprise distributed storage and processing frameworks designed to handle petabyte-scale structured and unstructured datasets across commodity hardware clusters, typically operating with HDFS replication factors of three and MapReduce or YARN resource management. Their primary commercial purpose centers on cost-effective batch processing, data lake architecture, and foundational analytics infrastructure for enterprise intelligence pipelines. Cloud-based deployment now captures the fastest expansion as organizations migrate from capital-intensive server farms to consumption-based models, while managed services segments concentrate margin pools through recurring operational contracts. Apache Spark integration within Hadoop ecosystems is displacing legacy MapReduce for in-memory processing, though Hive persists as the dominant SQL abstraction layer for batch reporting workloads.
The US Federal Trade Commission scrutinizes data aggregation practices that shape vendor selection criteria for Hadoop implementations, while Europe's GDPR mandates residency controls that complicate cross-border cluster architectures. China's Cybersecurity Law and GB standards enforce localized data processing requirements that fragment global platform standardization. Stakeholders must weigh sovereignty constraints against interoperability gains when architecting multi-region Hadoop estates.
Market Dynamics
Apache Spark is absorbing batch processing workloads from legacy MapReduce engines, compressing job completion times and forcing Hadoop vendors to rearchitect their distribution models around in-memory computation.
Growth Catalysts
- GDPR data residency mandates:European enterprises are deploying hybrid Hadoop clusters to maintain sovereign data lakes while enabling cross-border analytics.
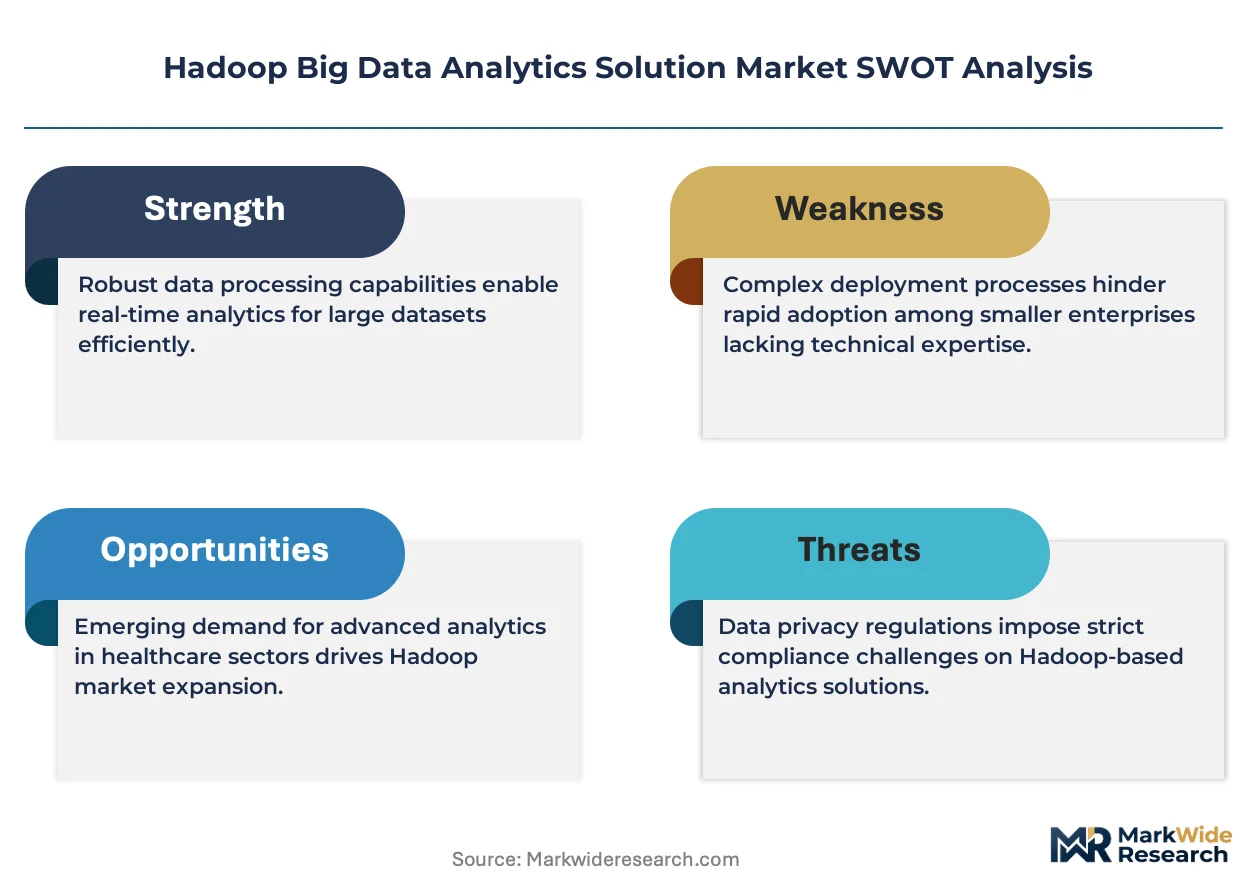
- Healthcare predictive analytics:Hospital systems are expanding Hadoop estates for population health modeling and genomic data processing.
- Petroleum reservoir simulation:Oil majors are commissioning distributed clusters for seismic data interpretation and production optimization.
Market Restraints
- Specialized talent scarcity:The shallow labor pool for YARN resource tuning and HDFS cluster administration inflates implementation timelines.
- Cloud storage cost volatility:S3-compatible object storage egress fees erode the cost advantage of hybrid architectures.
- Real-time processing substitution:Apache Kafka and Flink streaming platforms are capturing latency-sensitive workloads.
Strategic Opportunities
- India's data localization push:The RBI's payment data storage rules are creating demand for in-country Hadoop infrastructure.
- Edge-to-cloud orchestration:Converging Kubernetes container management with Hadoop data services opens manufacturing IoT deployments.
- Green financing disclosure:The EU CSRD mandates climate risk analytics that Hadoop lakes can aggregate across fragmented corporate systems.
Industry Challenges
- Certification timeline compression:SOC 2 Type II and ISO 27001 audits for managed Hadoop services now require 12-18 month preparation cycles.
- Skill pipeline gaps:Universities produce insufficient graduates with combined distributed systems and domain analytics expertise.
Report Scope
MarkWide Research| Attributes | Details |
|---|---|
| Report Title | Hadoop Big Data Analytics Solution Market |
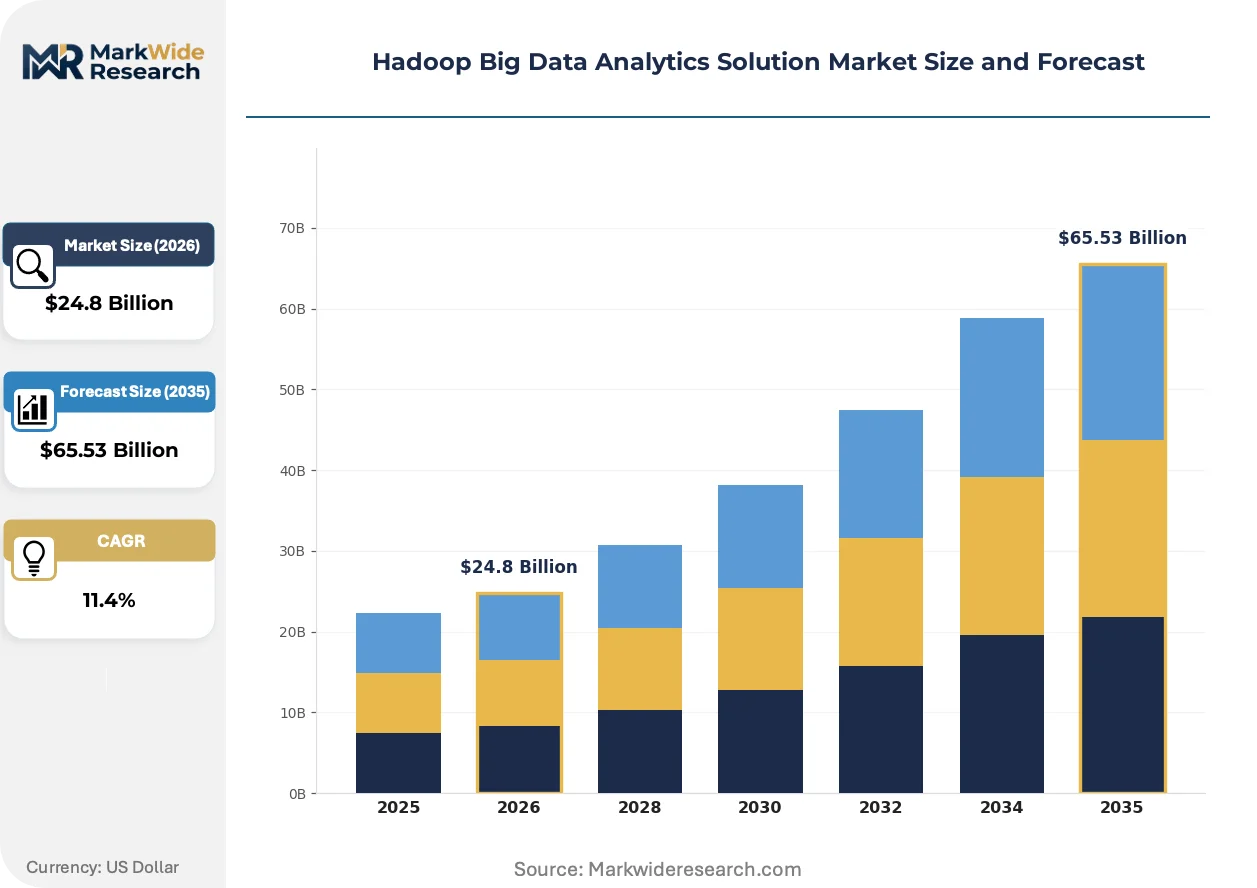
| Market Size in 2026 | $24.8 Billion |
| Market Size in 2035 | $65.53 Billion |
| CAGR (2026 – 2036) | 11.4% |
| Historical Year | 2020-2024 |
| Base Year | 2025 |
| Forecast Period | 2026-2036 |
| Segmentation | Deployment: On-Premises, Cloud-based, Hybrid, Managed Services End User: IT Sector, Healthcare, Retail, Manufacturing Technology: Apache Hadoop, Apache Spark, HBase, Hive Application: Data Warehousing, Real-time Analytics, ETL, Machine Learning |
| Companies Covered | Cloudera, Amazon Web Services, Hewlett Packard Enterprise, Microsoft, IBM, Oracle, SAP, Google, SAS Institute, Others |
| Regions Covered | North America: US, Canada, Mexico Europe: Germany, Italy, France, UK, Spain, Denmark, Sweden, Austria, Belgium, Finland, Turkey, Poland, Russia, Greece, Switzerland, Netherlands, Norway, Portugal, Rest of Europe Asia Pacific: China, Japan, India, South Korea, Indonesia, Malaysia, Kazakhstan, Taiwan, Vietnam, Thailand, Philippines, Singapore, Australia, New Zealand, Rest of Asia Pacific South America: Brazil, Argentina, Colombia, Chile, Peru, Rest of South America Middle East & Africa: Saudi Arabia, UAE, Qatar, South Africa, Israel, Kuwait, Oman, North Africa, West Africa, Rest of MEA |
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Hadoop Big Data Analytics Solution Market Trends and Innovations
Object storage integration is collapsing the traditional separation between compute and data layers, enabling ephemeral Hadoop clusters that spin up for specific analytical workloads.
Apache Spark is absorbing iterative machine learning training pipelines that previously required dedicated GPU clusters. Pharmaceutical firms are adopting Spark MLlib for molecular screening at scale. This convergence is absorbing budget allocations from standalone analytics appliances.
The EU AI Act's risk classification framework is forcing financial services Hadoop users to implement explainable data lineage. Banks must now demonstrate how training datasets flow through HDFS into model outputs. German regulators are demanding granular audit trails for credit scoring algorithms.
Consumption-based pricing for managed Hadoop services is displacing perpetual license models. Enterprise procurement teams are negotiating committed-use contracts with cloud providers rather than capitalizing on-premises hardware. This shift is most pronounced among mid-market retailers building customer 360 platforms.
Hadoop Big Data Analytics Solution Market Segmentation
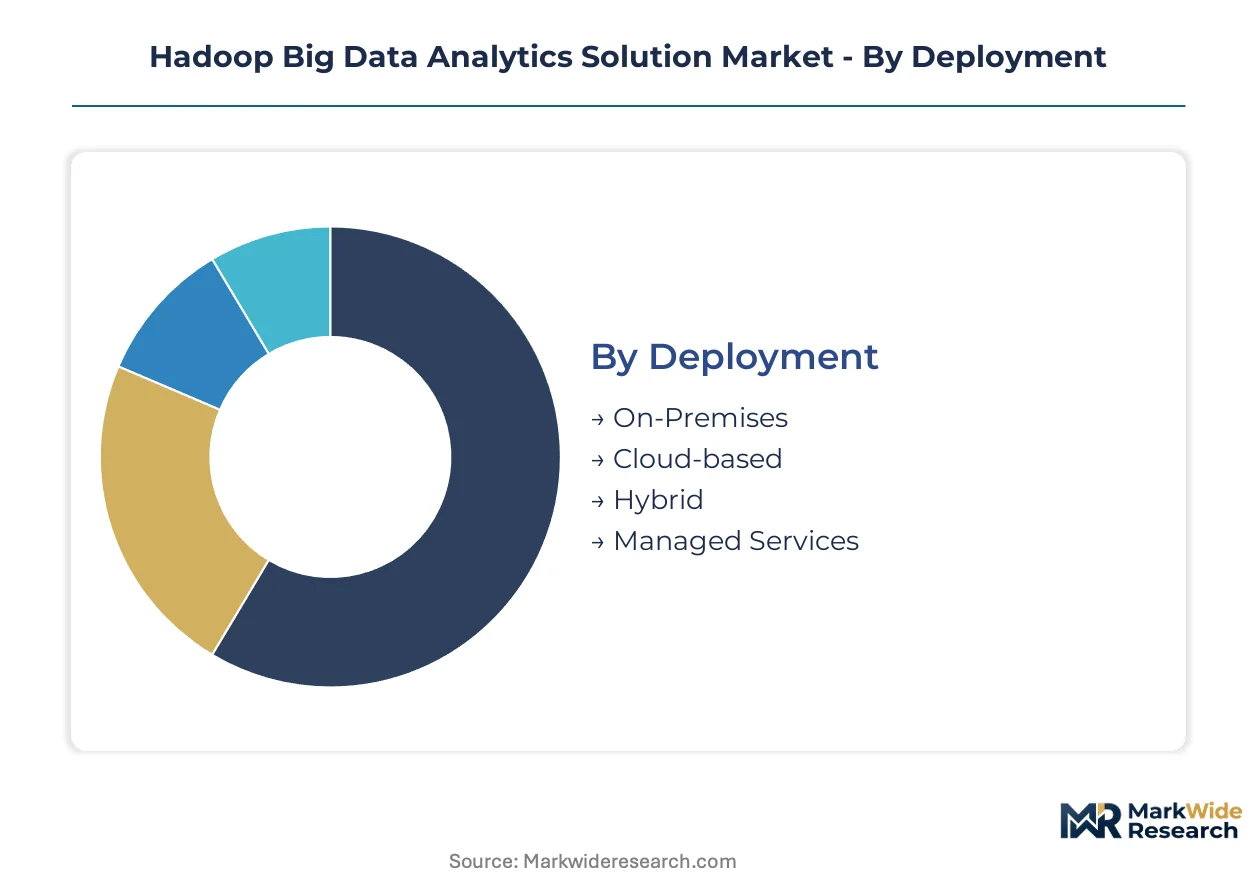
Hadoop deployments fragment across infrastructure philosophies, with vendor strategies diverging based on whether customers prioritize capital control, operational agility, or sovereign data constraints. Segment boundaries blur as hybrid architectures absorb features from pure cloud and on-premises extremes.
Deployment:
Supply concentration in hyperscale infrastructure is compressing margins for independent distribution vendors while elevating managed service providers with certified compliance stacks.
- On-Premises:Dedicated hardware clusters with HDFS replication across enterprise data centers deliver sub-millisecond latency for trading floors and manufacturing control systems. Financial institutions in Germany and the United States maintain these estates for regulatory audit trails under GDPR and SEC recordkeeping rules.
- Cloud-based:Consumption-metered object storage with ephemeral compute pools eliminates capacity planning cycles. Retailers building customer 360 platforms in China and India favor this model for seasonal demand spikes.
- Hybrid:Federated architectures partition sensitive data on-premises while bursting analytical workloads to public cloud. European pharmaceutical firms deploy this pattern to satisfy EMA clinical data residency requirements.
- Managed Services:Third-party operational accountability for patching, tuning, and 24/7 incident response. Mid-market enterprises without YARN expertise purchase these contracts to compress time-to-insight.
On-Premises absorbs the bulk of installed capacity; Cloud-based is expanding most quickly.
End User:
Application complexity and data gravity determine which sectors absorb premium consulting services versus commodity self-service platforms.
- IT Sector:Technology vendors and systems integrators operate the largest cluster footprints, often multi-tenant environments serving downstream clients. These deployments stress-test scalability for the entire ecosystem.
- Healthcare:Hospital systems process genomic sequences and population health records. HIPAA compliance and FDA 21 CFR Part 11 validation requirements shape procurement criteria.
- Retail:Omnichannel merchants unify clickstream, inventory, and supply chain signals. Demand concentrates in China and the United States where e-commerce penetration drives real-time personalization investments.
- Manufacturing:Industrial IoT sensor streams from predictive maintenance programs feed into quality control and supply chain optimization models.
IT Sector commands the deepest technical integration; Healthcare is climbing the fastest as regulatory frameworks mandate audit-ready data infrastructure.
Technology:
Processing engine selection now dictates storage format decisions, with in-memory frameworks displacing disk-bound batch systems in greenfield deployments.
- Apache Hadoop:The foundational distributed storage and batch processing framework with HDFS and MapReduce/YARN. Legacy enterprise data lakes in the United States and Germany continue expanding these estates.
- Apache Spark:In-memory computation engine with 10-100x speedup over MapReduce for iterative machine learning. Pharmaceutical molecular screening and financial risk simulations drive adoption.
- HBase:NoSQL database layer atop HDFS providing random read/write access for real-time serving workloads. Telecommunications firms deploy this for subscriber profile stores.
- Hive:SQL abstraction layer translating analytical queries into MapReduce or Tez execution plans. Business intelligence teams without Scala or Python skills depend on this interface.
Apache Hadoop retains the largest installed base; Apache Spark is gaining share fastest as GPU-accelerated training pipelines converge on unified data lakes.
Application:
Latency requirements and query patterns segment the market into batch-optimized versus stream-native architectural investments.
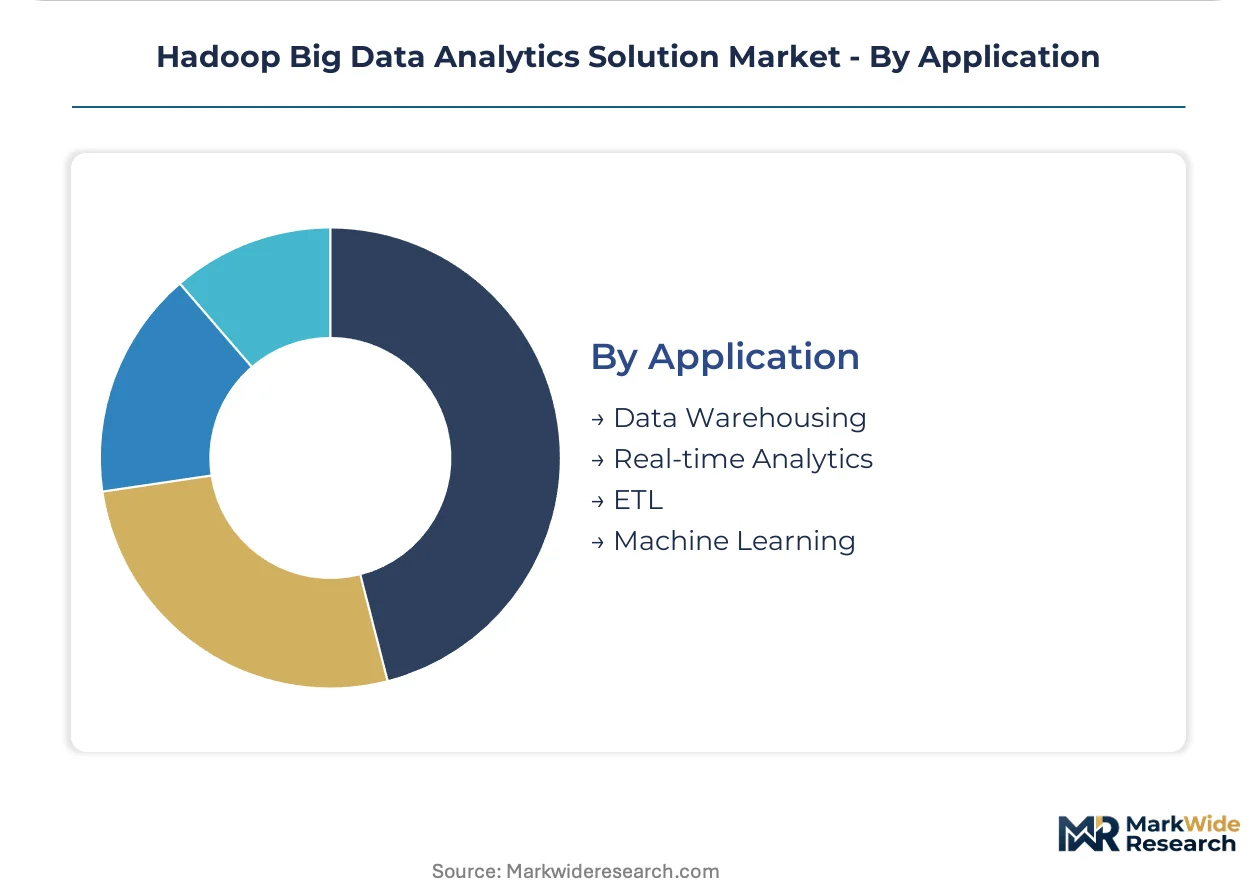
- Data Warehousing:Centralized repositories for structured historical analytics with Hive or Impala query engines. Enterprise finance departments in Germany and Japan standardize on these patterns.
- Real-time Analytics:Sub-second dashboard updates and operational decision support. Fraud detection systems at Indian and Brazilian payment processors require this capability.
- ETL:Extract-transform-load pipelines cleansing and normalizing source systems into analytical schemas. Data engineering teams spend 60-70% of Hadoop budgets on these workflows.
- Machine Learning:Feature engineering and model training at scale with Spark MLlib or third-party frameworks. Autonomous vehicle programs in the United States and China commission petabyte-scale clusters.
Data Warehousing absorbs the bulk of installed capacity; Machine Learning is expanding most quickly.
Need this report tailored to your region?
Request specific countries, segments, or companies — tailored to your requirements.
Regional Outlook
Silicon Valley's hyperscale data center clusters anchor North American capacity expansion for distributed analytics infrastructure. Frankfurt's banking district and Singapore's submarine cable landing points concentrate complementary demand nodes across three continents.
United States
Financial services firms in Manhattan and Chicago deploy sovereign Hadoop estates for SEC-mandated trade surveillance and risk model audit trails. The FTC scrutinizes data aggregation practices that shape vendor procurement criteria for cross-border cluster architectures. Northern Virginia's Ashburn-Loudoun corridor hosts the densest concentration of cloud-native Hadoop workloads worldwide.
China
State-owned petroleum majors commission petabyte-scale clusters for seismic interpretation and reservoir simulation in Sichuan and Xinjiang basins. The Cybersecurity Law and GB standards enforce localized data processing requirements that fragment global platform standardization. Hangzhou's e-commerce giants operate multi-tenant environments serving downstream retail analytics clients.
Germany
Automotive OEMs in Stuttgart and Munich build edge-to-cloud Hadoop fabrics for supply chain optimization and predictive quality control. GDPR data residency mandates compel hybrid cluster deployments to maintain sovereign data lakes while enabling cross-border analytics. Frankfurt's financial district anchors the deepest on-premises installed base for regulatory audit compliance.
India
Payment processors in Mumbai and Bangalore expand real-time fraud detection clusters to satisfy RBI data localization rules for transaction storage. The central bank's payment data storage mandates create demand for in-country Hadoop infrastructure with sub-second latency requirements. Hyderabad's pharmaceutical contract research organizations deploy genomic data lakes for population health modeling.
United Kingdom
London-based hedge funds and insurance underwriters maintain dedicated clusters for algorithmic trading and climate risk analytics. The EU AI Act's risk classification framework forces explainable data lineage implementations across HDFS estates. Cambridge's biotech corridor commissions distributed infrastructure for molecular screening pipelines.
Hadoop Big Data Analytics Solution Market Competitive Landscape
Global majors compete with regional champions across deployment architecture preferences, with hyperscale cloud providers absorbing cloud-native workloads while independent software vendors defend on-premises data center relationships. The vendor ecosystem organizes into three tiers: infrastructure-integrated hyperscalers, distribution-focused platform vendors, and managed service specialists. Consolidation pressure concentrates margin pools in recurring operational contracts. Strategic moves center on hybrid orchestration capabilities and sovereign compliance certifications.
Among infrastructure-integrated hyperscalers, Amazon Web Services and Microsoft exemplify the cloud-native archetype through managed platform offerings. Cloudera occupies a position representing the independent distribution model with unified governance capabilities. These three anchors illustrate the competitive tension between consumption-based elasticity and capital-controlled sovereignty that shapes procurement decisions across financial services and pharmaceutical verticals.
| Leading Market Players |
|---|
| Cloudera |
| Amazon Web Services |
| Hewlett Packard Enterprise |
| Microsoft |
| IBM |
| Oracle |
| SAP |
| SAS Institute |
| Others |
Pricing and Supply Chain Analysis
Apache Spark's displacement of MapReduce batch engines compresses job completion economics while concentrating supply leverage among hyperscalers with certified managed service stacks. This dual compression reshapes procurement negotiations as enterprises trade perpetual licenses for consumption-metered contracts tethered to sovereign compliance requirements.
Pricing Analysis
Service bundling separates SOC 2 Type II audit readiness from base platform fees, with European GDPR-compliant tiers commanding premiums over standard offerings. Three-tier pricing structure across premium, standard, and economy levels stratifies by certification depth and 24/7 incident response SLAs. Pricing pressure stems from cloud storage egress fee volatility eroding hybrid architecture cost advantages. Mid-market retailers without dedicated YARN expertise exhibit highest price sensitivity, while Frankfurt banking institutions prioritize sovereign audit trails over unit economics.
Supply Chain Analysis
Workforce scarcity for HDFS cluster administration and YARN resource tuning concentrates supply leverage in India, Ireland, and Poland where hyperscaler data centers anchor technical talent pipelines. Component dependencies span commodity x86 servers, high-density storage arrays, and specialized network fabrics for inter-node communication. Supply chain risk centers on single-source vulnerability for certified compliance engineering expertise required under EU AI Act explainability mandates. Distribution runs through direct enterprise sales teams for on-premises estates and self-service cloud marketplaces for ephemeral workloads.
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Analyst Recommendations
The Hadoop Big Data Analytics Solution Market functions as a cost-of-compliance story where GDPR data residency mandates and EU AI Act risk classification frameworks erect barrier-to-entry moats favoring certified incumbent platforms.
For Market Incumbents: Deepen hybrid orchestration capabilities to defend against cloud-native substitution, particularly Kubernetes-integrated data services capturing manufacturing IoT deployments. Anchor margin pools through recurring managed service contracts with embedded SOC 2 Type II and ISO 27001 certifications. Prioritize sovereign data lake architectures in Germany and India where RBI localization rules and EMA clinical data requirements concentrate procurement authority. For New Entrants and Emerging Players: Kubernetes-native data platform specialization offers white-space entry against legacy distribution vendors, targeting mid-market enterprises lacking internal YARN expertise. Edge-to-cloud orchestration for predictive maintenance programs in Stuttgart automotive supply chains represents the most penetrable application layer. Lead with consumption-based pricing and rapid time-to-insight guarantees rather than feature parity with Cloudera or Amazon Web Services. For Investors and Strategic Acquirers: Exit pathways concentrate in hyperscaler acquisition of compliance-certified managed service specialists with recurring revenue concentration above threshold levels. Long-term viability hinges on hybrid architecture dominance as pure cloud and pure on-premises extremes lose procurement relevance. Watch for inflection in EU CSRD climate risk analytics mandates triggering Hadoop lake modernization cycles across fragmented corporate systems.| Strategic Initiative | Industry Significance |
|---|---|
| Hybrid Data Platform Integration | Unifies edge and cloud governance for EMA clinical data residency compliance. |
| Managed Service Certification Investment | Compresses 12-18 month SOC 2 Type II preparation into competitive differentiation. |
| Spark-Native Architecture Migration | Absorbs pharmaceutical molecular screening budgets from standalone GPU clusters. |
| Sovereign Data Lake Deployment | Satisfies RBI payment data localization with sub-second fraud detection latency. |
| Kubernetes Container Orchestration | Opens manufacturing IoT sensor stream processing for predictive quality control. |
Research Methodology
Independent corroboration across platform engineering directors, enterprise IT procurement officers, cloud solution architects, and regulatory compliance leads underwrites the qualitative findings in this study. Primary fieldwork combined with secondary validation from hyperscaler capex disclosures, SEC 10-K infrastructure spend filings, and EMA clinical data guidance documents anchors the evidence base. Bottom-up cluster deployment sizing and top-down enterprise technology budget triangulation cross-check magnitude estimates.
Rate-of-change decomposition across deployment model, end-use vertical, processing engine technology, and application latency requirement segments structures the analytical framework. CAGRs derive from segment-level growth coefficient aggregation weighted by installed base evolution throughout the forecast period. Model inputs incorporate GDPR enforcement trajectory, RBI localization rule expansion, and Spark adoption curves in pharmaceutical molecular screening pipelines.
Several conditions sit outside the modeled scope, including abrupt cloud egress fee restructuring, breakthrough quantum computing substitution for reservoir simulation workloads, and geopolitical fragmentation of Apache open-source governance. Forecasts reflect documented assumptions about sovereign data architecture persistence and managed service margin pool concentration. Material deviation in EU AI Act enforcement intensity or hyperscaler certification timeline compression warrants pause and re-evaluation.
Need Custom Data?
Can't find what you're looking for? Our analysts can build a custom report tailored to your exact requirements.
1,000+
Global Clients
150+
Countries Covered
65,000+
Reports Available
Frequently Asked Questions
Why Work With MWR
Trusted by 1,000+ businesses across 150+ countries for high-stakes market decisions.
Ready to access intelligence that moves business?
Browse Reports →Trusted by Global Leaders
From Fortune-level organizations to global SMEs, we provide intelligence for high-stakes decisions.
Multi-Language Support
Research available in French, German, Spanish, Chinese, and more.
ISO & IAF Certified
Globally aligned quality standards ensuring methodological discipline and data integrity.
Competitive Relevance
Free inclusion of 3–4 additional companies of your choice in every report.
Customized Insights
Tailored intelligence for market entry, niche expansion, or competitive benchmarking.
Post-Sale Assistance
Dedicated coordination to help interpret findings and address queries post-delivery.
Cutting-Edge Methods
Structured data collection, advanced analytics, and expert validation for reliable forecasts.
Value for Investment
Credible, structured intelligence at a cost that makes strategic sense.
What Our Clients Say
My team needed the real numbers on AI spending for our Reinvention Services work. MarkWide delivered. No fluff, just a clear look at where the money is actually going. It saved us about three weeks of guesswork.
Accenture
We recently leaned on MarkWide Research for a deep dive into the evolving snacking habits within Southeast Asia. Their report on the premium biscuit segment was exceptionally detailed, providing us with the specific consumer sentiment data we needed to refine our regional flavor strategy. It wasn't just a data dump; the cultural nuances they captured helped us avoid several localization pitfalls.
Mondelez
Director of Global Consumer Insights
For a recent engagement in the automotive sector, we needed rigorous, independent verification of EV battery recycling capacities. MWR delivered a report that made our work easier. Their ability to segment the competitive landscape by chemical composition and regional throughput was exactly the kind of 'hard-to-find' intel that our team was looking for.
BCG
We were looking for a report on Xcelerator ecosystem's potential and got in touch with MarkWide's team through one of my old colleagues who worked with them in the past. Their research team was incredibly polite and were always available for us which was important for my team as this was a custom project. Their methodology for tracking industrial IoT adoption gave our R&D heads the clarity needed to prioritize our next-gen sensor development.
Siemens
Head of Industrial Digitalization
During a recent M&A project, we needed a fast, reliable breakdown of the Fintech landscape in Southeast Asia. MarkWide came through with a report that was actually readable and focused on the metrics that matter. It saved my team a good week of primary research, which, given our timelines, was a massive win.
KPMG
Advisory Partner
We tapped MarkWide Research for a deep dive into the ESG reporting software market. At Deloitte, our clients expect us to have the most current insights, and this report didn't disappoint. It provided a breakdown of the competitive field that was far more detailed than what we were expecting.
Deloitte
Lead Consultant, Sustainability Services
For our semiconductor division at Samsung, the supply chain forecast from MarkWide was incredibly useful. It provided a realistic outlook on raw material availability that helped us refine our production timelines. No fluff, just the data we needed to make a tough call.
Samsung
The value for our organization comes from three things: depth of research, specificity of segments and being easy to work with. As important as the first two are, the third can't be underestimated. MarkWide Research, maybe more than any other research vendor, wants to know what is top of mind for our team and what big questions we are grappling to answer. Their customer first approach and high value engagement model have given us great analysis and excellent value for money.
3M
I can share that it was a positive experience wherein MarkWide Research demonstrated flexibility to adapt to our needs and delivered an excellent report that fits all our requirements. Personally, I liked the timely follow up by the team and we will definitively reach out in case more research support is required.
VITO
Related Reports
Analytics
Advanced Analytics Market
Analytics
Global Analytics Software Market
Analytics
Enterprise Drone Analytics Software Market
Analytics
Manufacturing Predictive Analytics Market
Analytics
US Video Analytics Market
Analytics
Europe Big Data and Business Analytics Market
Analytics
Global System Monitoring Market
Analytics
Data Analytics Outsourcing Market
Analytics
Global Analytics Market
Analytics
Mobile Apps and Web Analytics Market
Analytics
Geospatial Analytics Market
Analytics
Self Service Analytics Market
Analytics
Global Subscription Analytics Software Market
Analytics
Global Digital Intelligence Platform Market
Analytics
Retail Analytics Market
Analytics
Workforce Analytics Market