
 GPU As a Service (Gpuaas) Market | 2026-2036
GPU As a Service (Gpuaas) Market Size, Share, and Industry Trends Forecast 2026-2036
GPU As a Service (Gpuaas) Market Analysis
Modular instance bundling is broadening buyer choice in GPUaaS procurement. Amazon Web Services leverages its Trainium and Inferentia silicon to anchor training workloads at scale. Microsoft competes through deep Azure integration with enterprise software stacks. CoreWeave specializes in bare-metal NVIDIA H100 configurations for AI-native startups.
GPU as a Service denotes cloud-delivered access to graphics processing units via virtualized or dedicated instances, typically provisioned through PCIe-connected accelerators with NVLink interconnects for multi-GPU parallelism, serving compute-intensive workloads without hardware ownership. Virtual GPU deployments capture expanding margin pools as mid-market buyers prioritize cost elasticity over dedicated silicon. Machine learning use cases lead segment velocity as foundation model training consumes the majority of provisioned tensor core hours.
The EU AI Act and GDPR jointly shape European GPUaaS demand by mandating data sovereignty and algorithmic transparency for high-risk applications. The US Federal Trade Commission scrutinizes cloud provider concentration under antitrust frameworks, while China's MIIT enforces GB standards for cross-border data flows affecting foreign-operated GPU clusters. Stakeholders must monitor how jurisdictional compute localization requirements reshape vendor selection criteria and infrastructure investment location.
Market Dynamics
GPUaaS demand concentrates around foundation model training workloads that consume tensor core hours at unprecedented scale, while supply scarcity of NVIDIA H100 and H200 accelerators creates allocation bottlenecks across cloud regions.
Growth Catalysts
- Generative AI training pipelines:Foundation model developers provision multi-thousand GPU clusters for pre-training runs, creating sustained demand for reserved instance contracts.
- EU AI Act risk-tiered obligations:High-risk AI system deployers in Europe must maintain algorithmic audit trails, pushing procurement toward certified GPUaaS infrastructure with sovereign data guarantees.
- NVIDIA NVLink interconnect proliferation:Multi-GPU parallelism via high-bandwidth fabric enables larger model training without external networking overhead, expanding viable workload scope.
Market Restraints
- Accelerator supply concentration:NVIDIA holds effective monopoly on training-optimized data center GPUs, creating single-source dependency for high-performance GPUaaS tiers.
- Power density constraints:Northern Virginia and Phoenix data center markets face utility interconnection delays that cap new GPU cluster deployment timelines.
- Export control friction:US Commerce Department licensing requirements restrict H100 and H200 shipments to Chinese entities, segmenting available supply pools.
Strategic Opportunities
- India cloud infrastructure buildout:Reliance Jio and Tata Communications are constructing domestic GPU clusters under PLI scheme incentives, creating localized alternatives to US-EU supply.
- Inference-at-edge deployment:Autonomous vehicle and robotics manufacturers seek sub-10ms latency GPU instances, opening distributed micro-datacenter partnerships.
- GDPR Article 44 transfer mechanism compliance:EU-based buyers require EU-only data processing guarantees, rewarding providers with exclusively European silicon footprints.
Industry Challenges
- CUDA software stack specialization:GPUaaS operations require engineers proficient in NVIDIA's proprietary parallel computing platform, tightening talent acquisition pipelines.
- Liquid cooling retrofit complexity:Legacy air-cooled facilities face 18-24 month infrastructure overhauls to support 700W-per-accelerator thermal loads.
Report Scope
MarkWide Research| Attributes | Details |
|---|---|
| Report Title | GPU As a Service (Gpuaas) Market |
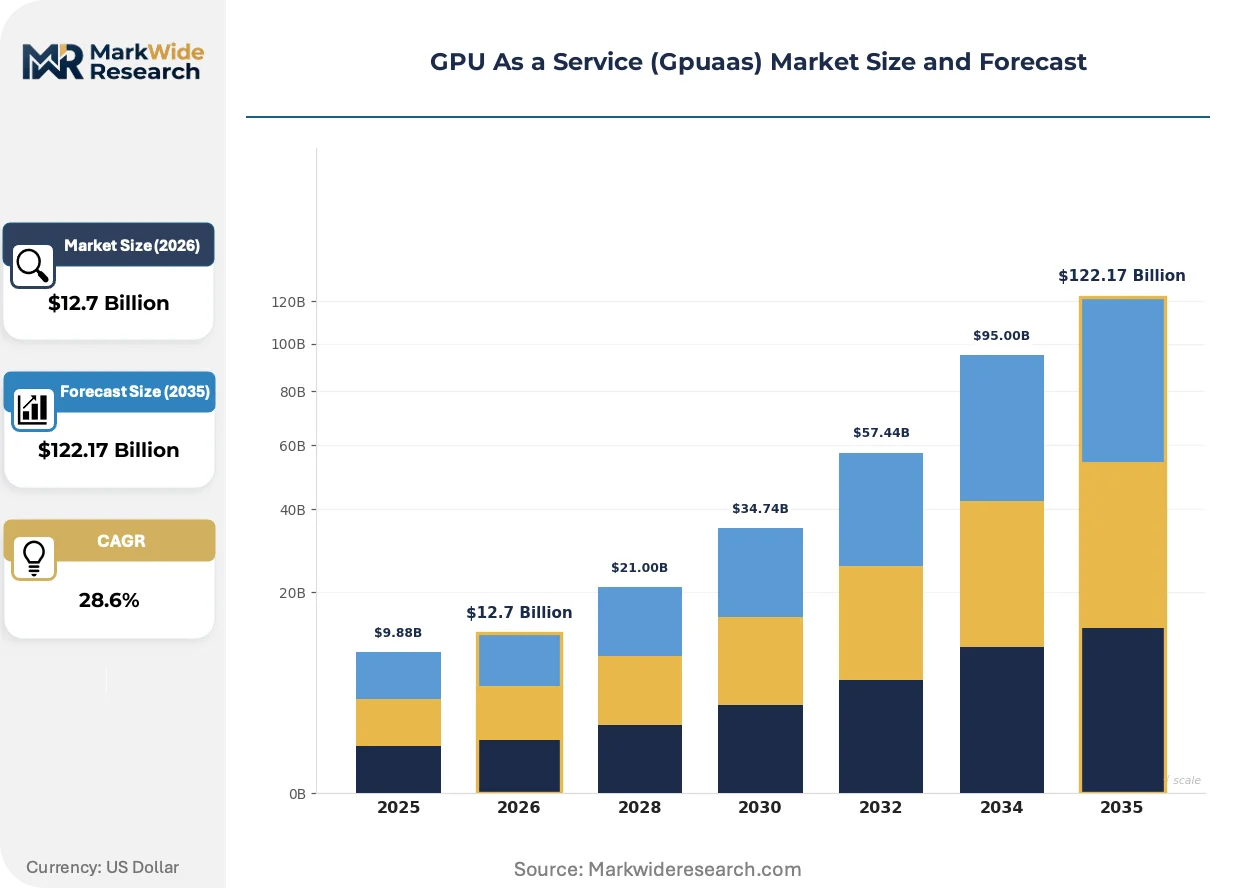
| Market Size in 2026 | $12.7 Billion |
| Market Size in 2035 | $122.17 Billion |
| CAGR (2026 – 2036) | 28.6% |
| Historical Year | 2020-2024 |
| Base Year | 2025 |
| Forecast Period | 2026-2036 |
| Segmentation | Service Type: Dedicated GPU, Virtual GPU, Cloud GPU, On-Premises GPU End User: Gaming Companies, Data Scientists, AI Researchers, Educational Institutions Deployment: Public Cloud, Private Cloud, Hybrid Cloud, Edge Computing Use Case: Machine Learning, Rendering, High-Performance Computing, Data Visualization |
| Companies Covered | Amazon Web Services, Microsoft, Google Cloud, IBM Corporation, Oracle, NVIDIA Corporation, CoreWeave, Alibaba Cloud, Lambda, Others |
| Regions Covered | North America: US, Canada, Mexico Europe: Germany, Italy, France, UK, Spain, Denmark, Sweden, Austria, Belgium, Finland, Turkey, Poland, Russia, Greece, Switzerland, Netherlands, Norway, Portugal, Rest of Europe Asia Pacific: China, Japan, India, South Korea, Indonesia, Malaysia, Kazakhstan, Taiwan, Vietnam, Thailand, Philippines, Singapore, Australia, New Zealand, Rest of Asia Pacific South America: Brazil, Argentina, Colombia, Chile, Peru, Rest of South America Middle East & Africa: Saudi Arabia, UAE, Qatar, South Africa, Israel, Kuwait, Oman, North Africa, West Africa, Rest of MEA |
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
GPU As a Service (Gpuaas) Market Emerging Trajectories
Silicon diversification and workload-specific optimization are fragmenting the homogeneous NVIDIA-centric GPUaaS stack, with cloud providers deploying custom accelerators and modular instance architectures to capture margin from specialized compute demands.
Multi-instance GPU partitioning is consolidating how mid-market buyers access compute resources. MLOps teams at Series B AI startups provision fractional A100 or H100 slices through Kubernetes-orchestrated containers rather than bare-metal rentals. This virtualization layer is consolidating procurement patterns around hourly spot pricing with preemption tolerance, compressing traditional reserved instance economics.
The EU AI Act's high-risk system documentation requirements are reshaping European infrastructure investment. Providers must maintain algorithmic audit logs, training data provenance records, and human oversight interface specifications for GPUaaS tenants deploying biometric or critical infrastructure AI. German automotive manufacturers and French healthcare AI developers are now mandating EU-sovereign compute clusters with ISO 27001 and EU Cloud Code of Conduct certification.
Consumption-based billing with workload-specific instance selection is displacing fixed-configuration contracts in North American enterprise procurement. FinOps teams at Fortune 500 companies benchmark training versus inference workloads to match Trainium, Inferentia, or T4 instances against NVIDIA alternatives. This optimization behavior concentrates among technology and financial services verticals with mature cloud cost management functions.
GPU As a Service (Gpuaas) Market Segmentation
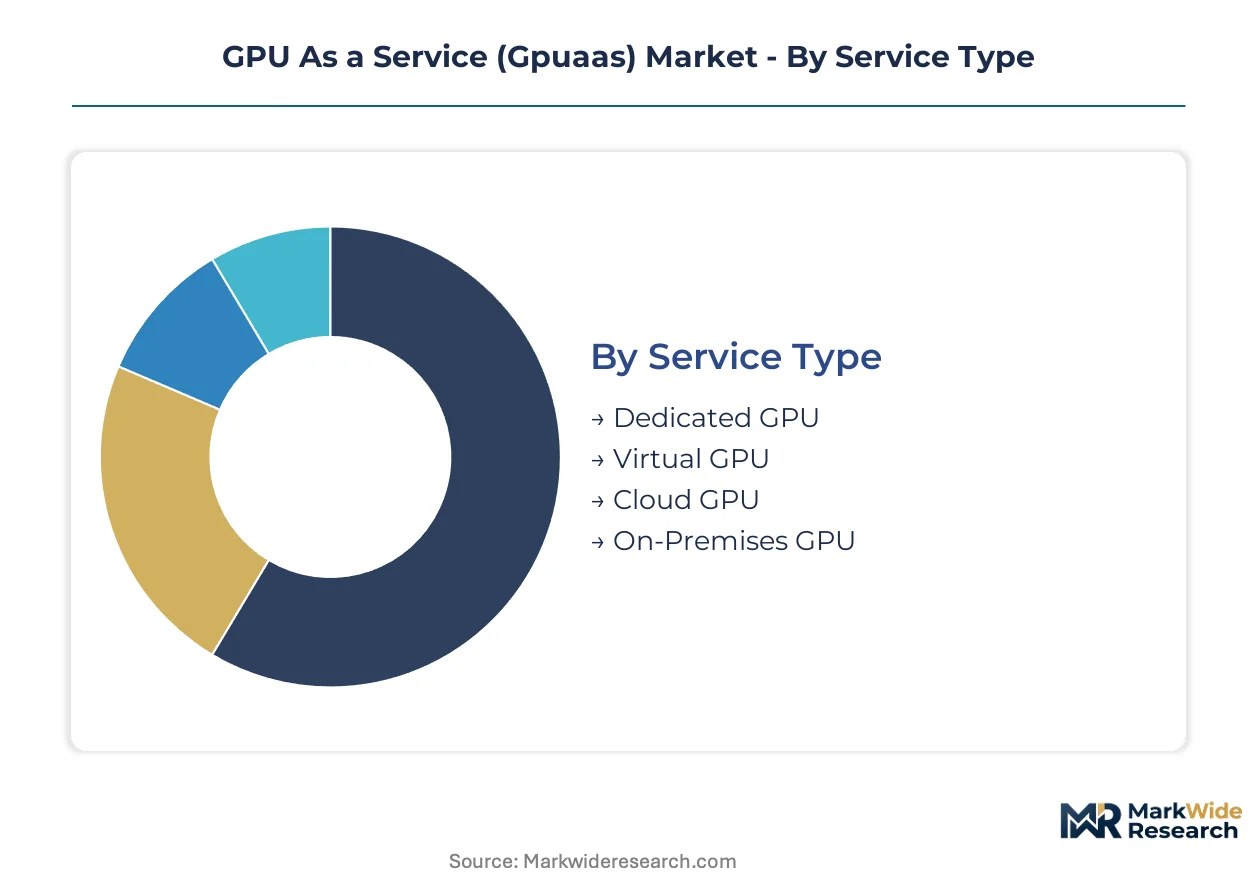
GPUaaS procurement patterns fragment across service tiers, end-user sophistication, and latency requirements. Buyers match infrastructure configurations to workload characteristics, creating distinct margin pools within each segment cluster.
Service Type:
Upgrade cycles differentiate service tier selection, with buyers migrating from shared virtual slices toward dedicated silicon as training pipelines mature.
- Dedicated GPU:Bare-metal NVIDIA H100 or H200 configurations provisioned through NVLink-enabled nodes for foundation model pre-training. Financial services firms in Northern Virginia anchor reserved instance demand here, prioritizing deterministic performance over cost elasticity.
- Virtual GPU:Fractional A100 partitioning via Kubernetes-orchestrated containers enables mid-market AI startups to access tensor cores without bare-metal commitment. MLOps teams at Series B companies drive hourly spot pricing adoption with preemption tolerance.
- Cloud GPU:Fully managed instances abstract hardware maintenance through hyperscaler orchestration layers.
- On-Premises GPU:Colocated accelerator racks within enterprise data centers retain data sovereignty for GDPR-sensitive workloads.
Volume placements concentrate in Virtual GPU; the faster expansion belongs to Dedicated GPU.
End User:
Customer sophistication determines procurement complexity, with research institutions favoring exploratory contracts against enterprise reserved commitments.
- AI Researchers:Academic and commercial labs provision ephemeral clusters for experimental architectures and ablation studies. Lawrence Livermore National Laboratory and similar HPC centers sustain demand for time-sliced supercomputing access with burst allocation protocols.
- Gaming Companies:Real-time rendering pipelines consume GPUaaS for asset generation and cloud gaming infrastructure without capital-intensive studio buildouts. Unity and Unreal Engine workflows concentrate demand in Oregon and Northern Virginia availability zones.
- Data Scientists:Enterprise analytics teams leverage managed notebook environments with pre-configured CUDA stacks.
- Educational Institutions:University computer science departments access subsidized educational tiers for curriculum-aligned coursework.
Contract values peak with AI Researchers; Educational Institutions gain share fastest through cloud education partnerships.
Deployment:
Latency tolerance and compliance posture shape infrastructure location decisions across the deployment spectrum.
- Public Cloud:Hyperscaler-managed availability zones deliver elastic scale for variable training workloads. AWS, Azure, and Google Cloud anchor capacity in Ashburn, Virginia and Hillsboro, Oregon with direct liquid cooling infrastructure.
- Edge Computing:Sub-10ms latency instances serve autonomous vehicle perception pipelines and robotics control systems. Waymo and similar manufacturers deploy micro-datacenter partnerships for inference-at-edge requirements.
- Private Cloud:Single-tenant GPU clusters satisfy German automotive manufacturers mandating EU-sovereign compute under ISO 27001 certification.
- Hybrid Cloud:Burst capacity configurations extend on-premises training to cloud overflow during peak demand windows.
Public Cloud absorbs the majority of provisioned tensor core hours; Edge Computing climbs the fastest on autonomous system deployment timelines.
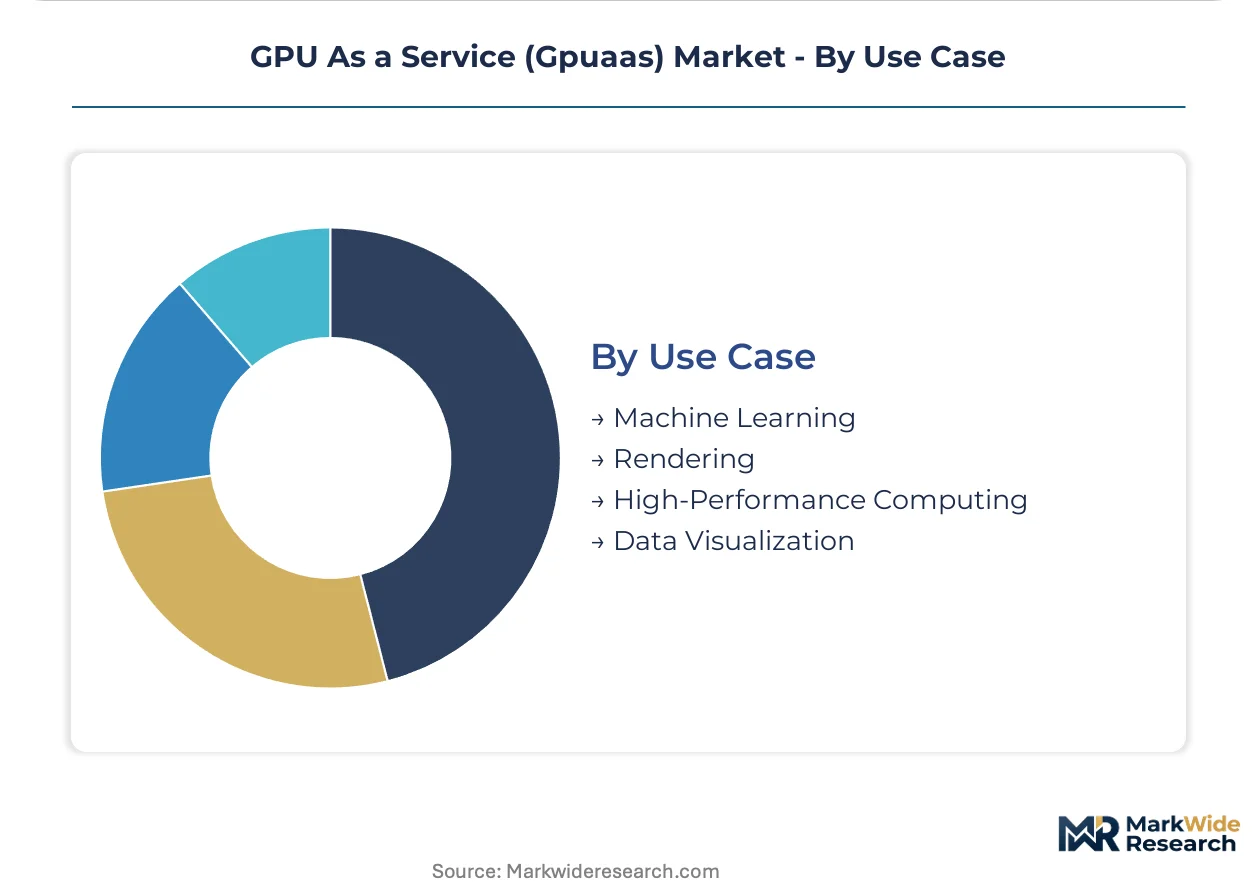
Use Case:
Workload computational intensity creates divergent instance selection patterns across the use case matrix.
- Machine Learning:Foundation model training consumes multi-thousand GPU clusters with sustained tensor core utilization. Pre-training runs for large language models dominate reserved instance economics across all major cloud regions.
- High-Performance Computing:Climate simulation and molecular dynamics workloads leverage FP64 precision capabilities in NVIDIA A100 and H100 configurations.
- Rendering:Media production studios access ephemeral GPU farms for final frame generation and real-time virtual production environments.
- Data Visualization:Interactive analytics dashboards drive intermittent GPU acceleration for geospatial and biomedical imaging applications.
Machine Learning commands the steepest infrastructure investment; Rendering demonstrates the most price-sensitive spot market behavior.
Need this report tailored to your region?
Request specific countries, segments, or companies — tailored to your requirements.
Regional Outlook
Data center tax incentives in Northern Virginia's Loudoun County anchor the world's densest GPUaaS concentration, with enterprise demand cascading across hyperscaler availability zones in Hillsboro, Frankfurt, and Singapore.
United States
Foundation model developers at OpenAI and Anthropic provision multi-thousand H100 clusters through reserved instance contracts. The Federal Trade Commission scrutinizes cloud provider concentration under antitrust frameworks. Northern Virginia's "Data Center Alley" in Ashburn and Loudoun County hosts over 70% of national GPUaaS capacity with direct liquid cooling infrastructure.
Germany
Automotive manufacturers mandate EU-sovereign compute for autonomous driving AI development under GDPR Article 44 transfer restrictions. The EU AI Act's high-risk system documentation requirements push procurement toward ISO 27001-certified infrastructure. Frankfurt's Rhine-Main metropolitan region anchors continental GPU cluster deployment with dedicated sovereign cloud zones.
China
Domestic AI labs accelerate training pipelines on indigenously designed accelerators as US Commerce Department export controls restrict H100 and H200 shipments. MIIT enforces GB standards for cross-border data flows affecting foreign-operated GPU clusters. Beijing-Tianjin-Hebei's Zhongguancun technology corridor concentrates state-backed GPU infrastructure investment.
India
Reliance Jio and Tata Communications construct domestic GPU clusters under PLI scheme incentives to serve foundation model developers seeking alternatives to US-EU supply. The country's national data protection authority mandates data localization for sensitive AI workloads. Mumbai-Pune and Bengaluru-Hyderabad corridors anchor cloud infrastructure buildout with dedicated AI-focused data centers.
United Kingdom
Financial services firms in the City of London provision GPUaaS for real-time risk modeling and algorithmic trading infrastructure. The Information Commissioner's Office enforces GDPR-aligned data processing guarantees for AI system deployers. Slough's trading estate and London Docklands data center zones concentrate fintech-driven GPU demand with sub-5ms latency requirements.
GPU As a Service (Gpuaas) Market Vendor Landscape
Diversified conglomerates compete with focused pure-play specialists across tiered service configurations. Hyperscalers leverage existing enterprise relationships and global fiber networks to anchor training workload contracts. The market structure fragments across three strategic archetypes: full-stack cloud providers, bare-metal GPU specialists, and silicon-integrated platform operators. Dominant competitive moves include strategic partnerships with foundation model developers and geographic expansion into sovereign cloud zones.
Within the bare-metal specialist tier, CoreWeave and Lambda exemplify pure-play positioning with NVIDIA-centric infrastructure configurations. Among full-stack hyperscalers, Amazon Web Services anchors market presence through Trainium and Inferentia silicon integration. These three companies occupy distinct competitive positions: CoreWeave represents startup-focused bare-metal provisioning, Lambda exemplifies researcher-oriented access models, and Amazon Web Services anchors enterprise-scale reserved instance economics.
| Leading Market Players |
|---|
| Amazon Web Services |
| Microsoft |
| Google Cloud |
| IBM Corporation |
| Oracle |
| NVIDIA Corporation |
| CoreWeave |
| Alibaba Cloud |
| Lambda |
| Others |
Supply Flow & Price Mechanics
CUDA-certified engineering talent concentration in Northern Virginia and San Francisco Bay Area widens pricing-tier spreads, as hyperscalers absorb premium labor costs into reserved instance rates while bare-metal specialists pass through spot-market discounts to preemption-tolerant buyers.
Pricing Analysis
Lead-time-driven pricing stratifies across reserved, on-demand, and spot tiers, with foundation model developers paying premiums for guaranteed H100 cluster availability while Series B startups capture discounts through interruptible instances. Certification level—ISO 27001 and EU Cloud Code of Conduct—commands tier separation alongside NVLink-enabled node density. Cost compression in virtual GPU tiers intensifies as Kubernetes orchestration commoditizes fractional A100 access. Educational institutions exhibit highest price sensitivity against financial services firms anchoring reserved contracts.
Supply Chain Analysis
NVIDIA H100 and H200 accelerator supply rests on TSMC's advanced packaging capacity in Taiwan, with memory HBM3e sourcing concentrated in South Korea's SK Hynix and Samsung facilities. CoWoS interposer manufacturing and high-bandwidth memory stacks constitute critical input dependencies. Single-source vulnerability around NVIDIA's CUDA software ecosystem creates lock-in risk across downstream cloud orchestration layers. Distribution runs through hyperscaler direct procurement channels and bare-metal specialist leasing arrangements.
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Analyst Recommendations
GPU as a Service infrastructure is becoming a vertical-integration race, with providers pursuing captive silicon design and direct liquid cooling deployment to escape NVIDIA supply constraints and power density bottlenecks.
For Market Incumbents: Acquire sovereign cloud certification assets to defend European enterprise contracts against GDPR Article 44 transfer restrictions. Anchor reserved instance economics through long-term NVIDIA allocation agreements while building in-house accelerator design capabilities via Trainium-class silicon investments. For New Entrants and Emerging Players: Mid-market AI startups with preemption-tolerant training pipelines represent the most penetrable buyer archetype. Capture share through Kubernetes-native fractional GPU provisioning with sub-hour billing granularity. Differentiate via specialized inference-at-edge micro-datacenter partnerships for autonomous vehicle developers. For Investors and Strategic Acquirers: Re-rating potential sits with bare-metal specialists possessing direct NVIDIA allocation relationships given foundation model developers' insatiable demand for multi-thousand GPU clusters. Long-term viability hinges on backward integration into custom silicon or cooling infrastructure. Watch hyperscaler capex disclosure inflections as demand signal.| Strategic Initiative | Industry Significance |
|---|---|
| Custom Silicon Development | AWS Trainium and Inferentia deployment reduces NVIDIA dependency for training workloads. |
| Sovereign Cloud Certification | ISO 27001 and EU Cloud Code of Conduct credentials unlock German automotive manufacturer contracts. |
| Liquid Cooling Infrastructure | Direct-to-chip thermal management enables 700W-per-accelerator H200 deployment in legacy facilities. |
| Edge Micro-Datacenter Partnerships | Sub-10ms latency instances serve Waymo-class autonomous vehicle perception pipelines. |
| Multi-Instance GPU Partitioning | Kubernetes-orchestrated fractional A100 access captures mid-market AI startup procurement. |
Methodological Framework
Document review covered hyperscaler capex disclosures, NVIDIA supply allocation reports, and EU AI Act implementation guidance, complemented by interviews with cloud infrastructure procurement officers, MLOps engineering leads at Series B AI startups, data center facility managers, and regulatory compliance specialists. Secondary validation drew from SEC 10-K infrastructure investment filings, customs accelerator import records, and datacenter tax incentive databases. Bottom-up instance-hour provisioning estimates triangulated against top-down cloud revenue attribution.
Segment-level outputs across service type, end user sophistication, deployment architecture, and use case intensity informed the analytical framework over the projection horizon. CAGRs derived from elasticity-adjusted demand curves incorporating foundation model training run frequency and inference-at-edge penetration trajectories. NVIDIA supply allocation constraints and EU sovereign compute mandates served as industry-specific forecast inputs.
Revisions become necessary when export control licensing regimes tighten, alternative accelerator architectures achieve CUDA compatibility, or utility interconnection delays extend beyond modeled timelines. A small set of named triggers—NVIDIA supply allocation shifts, EU AI Act enforcement intensity, and hyperscaler custom silicon deployment velocity—warrants ongoing watch.
Need Custom Data?
Can't find what you're looking for? Our analysts can build a custom report tailored to your exact requirements.
1,000+
Global Clients
150+
Countries Covered
65,000+
Reports Available
Frequently Asked Questions
Why Work With MWR
Trusted by 1,000+ businesses across 150+ countries for high-stakes market decisions.
Ready to access intelligence that moves business?
Browse Reports →Trusted by Global Leaders
From Fortune-level organizations to global SMEs, we provide intelligence for high-stakes decisions.
Multi-Language Support
Research available in French, German, Spanish, Chinese, and more.
ISO & IAF Certified
Globally aligned quality standards ensuring methodological discipline and data integrity.
Competitive Relevance
Free inclusion of 3–4 additional companies of your choice in every report.
Customized Insights
Tailored intelligence for market entry, niche expansion, or competitive benchmarking.
Post-Sale Assistance
Dedicated coordination to help interpret findings and address queries post-delivery.
Cutting-Edge Methods
Structured data collection, advanced analytics, and expert validation for reliable forecasts.
Value for Investment
Credible, structured intelligence at a cost that makes strategic sense.
What Our Clients Say
My team needed the real numbers on AI spending for our Reinvention Services work. MarkWide delivered. No fluff, just a clear look at where the money is actually going. It saved us about three weeks of guesswork.
Accenture
We recently leaned on MarkWide Research for a deep dive into the evolving snacking habits within Southeast Asia. Their report on the premium biscuit segment was exceptionally detailed, providing us with the specific consumer sentiment data we needed to refine our regional flavor strategy. It wasn't just a data dump; the cultural nuances they captured helped us avoid several localization pitfalls.
Mondelez
Director of Global Consumer Insights
For a recent engagement in the automotive sector, we needed rigorous, independent verification of EV battery recycling capacities. MWR delivered a report that made our work easier. Their ability to segment the competitive landscape by chemical composition and regional throughput was exactly the kind of 'hard-to-find' intel that our team was looking for.
BCG
We were looking for a report on Xcelerator ecosystem's potential and got in touch with MarkWide's team through one of my old colleagues who worked with them in the past. Their research team was incredibly polite and were always available for us which was important for my team as this was a custom project. Their methodology for tracking industrial IoT adoption gave our R&D heads the clarity needed to prioritize our next-gen sensor development.
Siemens
Head of Industrial Digitalization
During a recent M&A project, we needed a fast, reliable breakdown of the Fintech landscape in Southeast Asia. MarkWide came through with a report that was actually readable and focused on the metrics that matter. It saved my team a good week of primary research, which, given our timelines, was a massive win.
KPMG
Advisory Partner
We tapped MarkWide Research for a deep dive into the ESG reporting software market. At Deloitte, our clients expect us to have the most current insights, and this report didn't disappoint. It provided a breakdown of the competitive field that was far more detailed than what we were expecting.
Deloitte
Lead Consultant, Sustainability Services
For our semiconductor division at Samsung, the supply chain forecast from MarkWide was incredibly useful. It provided a realistic outlook on raw material availability that helped us refine our production timelines. No fluff, just the data we needed to make a tough call.
Samsung
The value for our organization comes from three things: depth of research, specificity of segments and being easy to work with. As important as the first two are, the third can't be underestimated. MarkWide Research, maybe more than any other research vendor, wants to know what is top of mind for our team and what big questions we are grappling to answer. Their customer first approach and high value engagement model have given us great analysis and excellent value for money.
3M
I can share that it was a positive experience wherein MarkWide Research demonstrated flexibility to adapt to our needs and delivered an excellent report that fits all our requirements. Personally, I liked the timely follow up by the team and we will definitively reach out in case more research support is required.
VITO
Related Reports
Cloud Computing
Brazil Cloud Computing Market
Cloud Computing
Distributed Cloud System Market
Cloud Computing
Philippines ICT Market
Cloud Computing
Europe Cloud Computing Market
Cloud Computing
Europe Cloud Managed Networking Market
Cloud Computing
Platform As a Service (Paas) Market
Cloud Computing
Cloud Computing Services Market
Cloud Computing
Dbaas and Cloud Database Market
Cloud Computing
Multi-Cloud Architecture Market
Cloud Computing
Public Cloud Application Services Market
Cloud Computing
Cloud Services Market
Cloud Computing
Cloud Calling Market
Cloud Computing
Canada Cloud Computing Market
Cloud Computing
Private Cloud Market
Cloud Computing
Serverless Computing Market
Cloud Computing
Government Cloud Computing Market