
 Global AI Training Dataset Market | 2026-2036
Global AI Training Dataset Market Size, Share, and Industry Trends Forecast 2026-2036
Global AI Training Dataset Market Foresight
Raw data collection margins is narrowing as value accrues to annotation, validation, and synthetic generation layers. Scale AI dominates the frontier model data pipeline through its RLHF contractor network and government contracts. Appen sustains enterprise relationships through its crowd-sourced linguist pool across 170 countries. Defined.ai differentiates via its intellectual property marketplace, licensing speech and NLP datasets to European telecom and banking clients.
AI training datasets comprise curated, labeled, and augmented digital corpora—images, text, audio, video, and sensor streams—processed through annotation pipelines, quality assurance workflows, and bias detection algorithms to render machine-readable signals for model optimization. Image data for computer vision commands premium pricing due to polygonal annotation complexity and medical imaging compliance overhead, while text corpora for natural language processing expand fastest as multilingual large language model development accelerates across research institutes and tech startups. Cloud-based deployment absorbs the majority of new spending, though edge computing configurations gain traction among automotive OEMs requiring localized training loops for autonomous fleet validation.
The European Union AI Act and GDPR constrain cross-border data transfers and mandate transparency documentation for training data provenance, compelling vendors to establish EU-local annotation centers and audit trails. The United States lacks comprehensive federal AI legislation, though the FDA regulates machine learning-enabled medical devices and the NHTSA mandates dataset reporting for autonomous vehicle safety assessments. Stakeholders must monitor emerging sector-specific requirements in healthcare and transportation, as regulatory fragmentation between jurisdictions reshapes sourcing strategies and compliance cost structures.
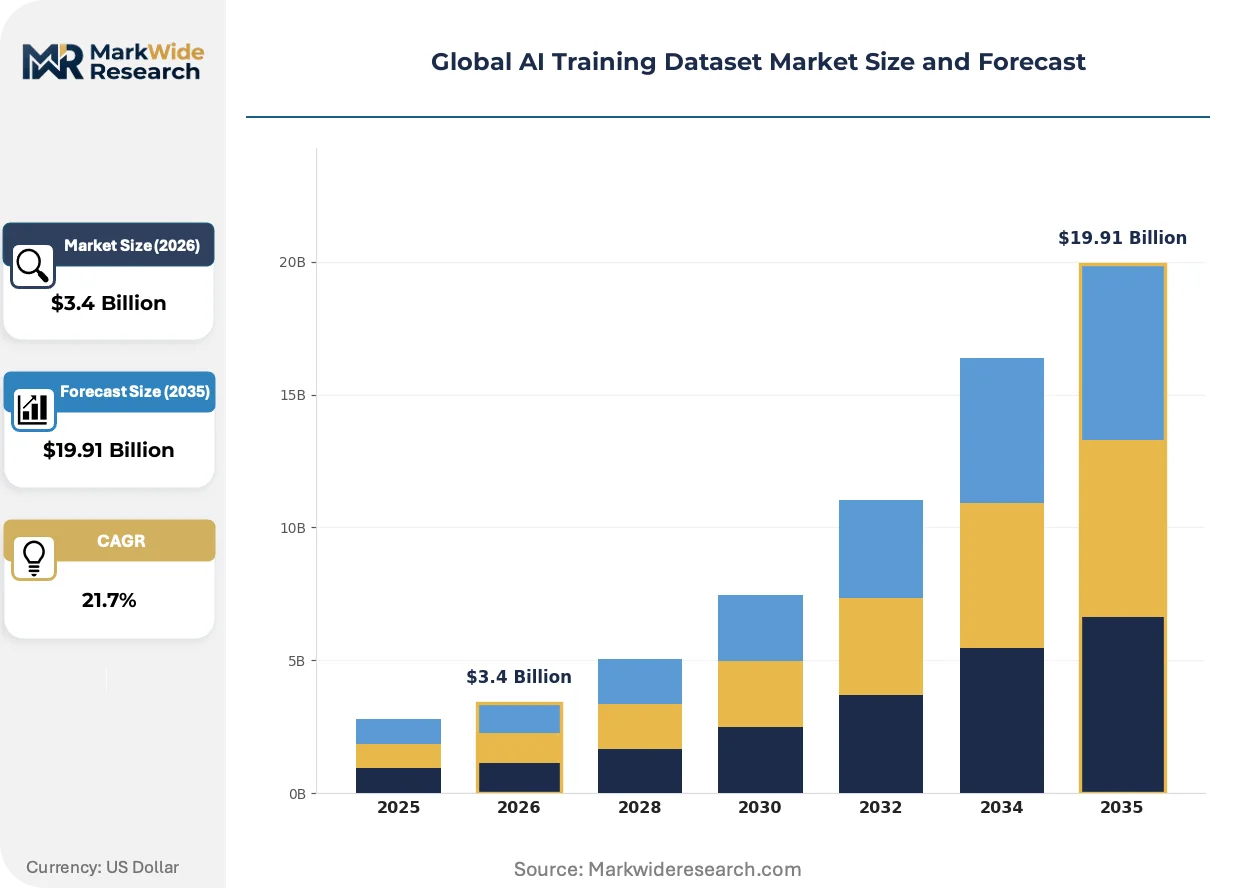
Market Dynamics
Value migration from raw data harvesting toward annotation, validation, and synthetic generation layers is compressing margins at the collection tier while concentrating pricing power among pipeline orchestrators. Regulatory fragmentation between the EU AI Act's risk-based documentation mandates and the US sector-specific approach is forcing vendors to maintain dual compliance architectures.
Growth Catalysts
- Autonomous Vehicle Sensor Corpora:Fleet operators in California, Arizona, and Germany are procuring multi-modal labeled datasets combining LiDAR point clouds, camera feeds, and radar streams to train perception models for urban navigation scenarios.
- EU AI Act Documentation Mandates:High-risk application providers must maintain audit trails for training data provenance, creating sustained demand for EU-local annotation centers with chain-of-custody capabilities.
- Synthetic Data Generation Pipelines:Neural rendering engines are producing photorealistic training samples for rare edge cases, reducing dependency on expensive physical data capture for medical imaging and industrial defect detection.
Market Restraints
- Specialized Annotator Labor Scarcity:Polygonal segmentation for medical imaging and 3D point cloud labeling requires certified technicians, constraining throughput in Germany, Japan, and the United States.
- Cross-Border Transfer Friction:GDPR and emerging data localization laws in India and China fragment global dataset assembly, forcing redundant infrastructure deployment.
- Quality Assurance Cost Escalation:Human-in-the-loop validation for high-stakes applications consumes 35-50% of annotation budgets, limiting margin expansion.
Strategic Opportunities
- Federated Learning Architectures:Edge-computing configurations allow automotive OEMs to train models on distributed fleet data without centralizing sensitive sensor streams, opening sovereign cloud partnerships in France and South Korea.
- Multilingual NLP Corpora:Low-resource language coverage gaps in Arabic, Swahili, and Indic languages present first-mover advantages for academic consortiums and regional telecom operators.
- Biometric Consent Frameworks:India's DPDP Act and Brazil's LGPD are mandating granular consent management for facial and voice datasets, creating compliance-as-a-service revenue streams.
Industry Challenges
- RLHF Specialist Recruitment:Reinforcement learning from human feedback requires domain experts capable of evaluating complex reasoning chains, creating bidding wars among frontier model labs.
- Intellectual Property Contamination:Web-scraped training corpora carry latent copyright exposure, forcing costly provenance audits and licensed content substitution.
Report Scope
MarkWide Research| Attributes | Details |
|---|---|
| Report Title | Global AI Training Dataset Market |
| Market Size in 2026 | $3.4 Billion |
| Market Size in 2035 | $19.91 Billion |
| CAGR (2026 – 2036) | 21.7% |
| Historical Year | 2020-2024 |
| Base Year | 2025 |
| Forecast Period | 2026-2036 |
| Segmentation | Data Type: Image, Text, Audio, Video, Sensor Data Use Case: Natural Language Processing, Computer Vision, Speech Recognition, Predictive Analytics, Autonomous Systems End User: Tech Startups, Research Institutes, Automotive OEMs, Financial Services Firms, E-commerce Companies Deployment Type: Cloud-Based, On-Premises, Hybrid, Edge Computing |
| Companies Covered | Cogito Tech, Twine AI, Appen, Shaip, Nexdata, Scale AI, iMerit, Defined.ai, TELUS International, Others |
| Regions Covered | North America: US, Canada, Mexico Europe: Germany, Italy, France, UK, Spain, Denmark, Sweden, Austria, Belgium, Finland, Turkey, Poland, Russia, Greece, Switzerland, Netherlands, Norway, Portugal, Rest of Europe Asia Pacific: China, Japan, India, South Korea, Indonesia, Malaysia, Kazakhstan, Taiwan, Vietnam, Thailand, Philippines, Singapore, Australia, New Zealand, Rest of Asia Pacific South America: Brazil, Argentina, Colombia, Chile, Peru, Rest of South America Middle East & Africa: Saudi Arabia, UAE, Qatar, South Africa, Israel, Kuwait, Oman, North Africa, West Africa, Rest of MEA |
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Global AI Training Dataset Market Shifts & Advancements
Neural rendering and diffusion-based synthesis are displacing physical data capture for rare scenario coverage. Regulatory documentation requirements are hardening into technical specifications. Buyer procurement patterns are fragmenting across hyperscaler direct contracts, specialized annotation boutiques, and open-source community contributions.
Diffusion models trained on 3D scene graphs are digitizing synthetic environment generation for autonomous vehicle training, reducing the marginal cost of edge-case scenarios by orders of magnitude. Automotive OEMs in Germany and Japan are integrating these pipelines into continuous validation loops. The technology is digitizing what was previously a physical logistics constraint—rare weather and collision scenarios—into scalable software production.
The EU AI Act's risk-based classification system is mandating technical documentation for training data provenance, quality assurance methodologies, and bias mitigation measures. Vendors serving high-risk categories—medical diagnosis, credit scoring, biometric identification—must maintain EU-local annotation centers with audit trails. Healthcare AI developers in France and the Netherlands are restructuring supplier contracts to embed compliance documentation into deliverables.
Enterprise buyers are unbundling annotation services from end-to-end model development contracts, establishing direct relationships with specialized providers for domain-specific tasks. Financial services firms in Singapore and the United Kingdom are procuring linguistic datasets separately from computer vision pipelines, disintermediating full-service vendors. This pattern is most visible in regulated industries where internal data science teams retain model architecture control while outsourcing labor-intensive labeling.
Global AI Training Dataset Market Segmentation
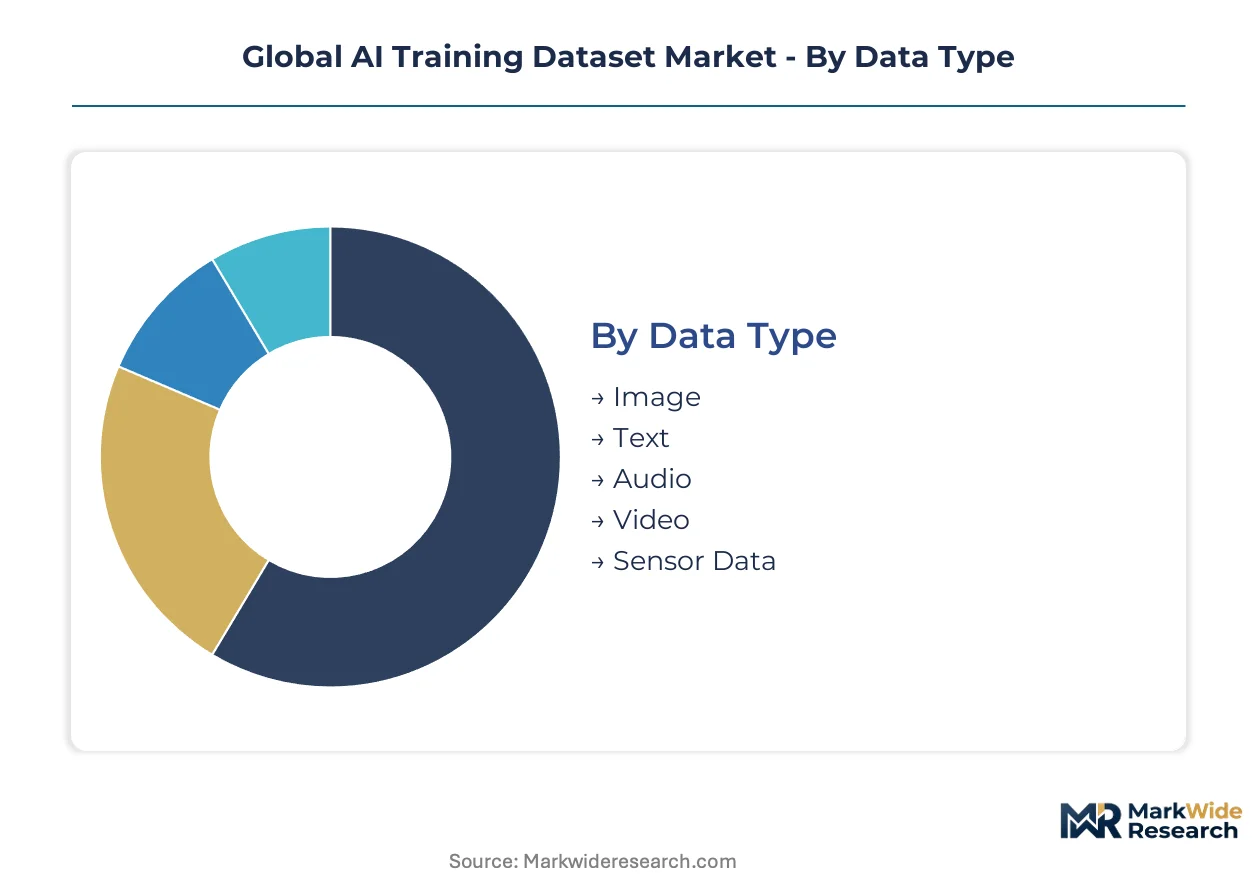
Segmentation in AI training datasets reveals where value accrues across the pipeline. Cycle times vary dramatically: sensor corpora for autonomous vehicles refresh quarterly as fleet data accumulates, while foundational text corpora for large language models turn over annually. Procurement patterns diverge accordingly.
Data Type:
Image data cycles fastest through annotation pipelines due to continuous computer vision model iteration, while audio datasets for speech recognition exhibit slower refresh rates tied to linguistic stability.
- Image:Polygonal segmentation and pixel-level annotation for medical imaging and autonomous navigation command premium pricing. Demand concentrates in California and Germany where automotive OEMs and healthcare AI developers procure labeled radiology scans and urban driving scenarios.
- Text:Multilingual corpora spanning web-scale crawls, curated books, and synthetic dialogue generation for large language model pre-training. Expansion concentrates fastest among research institutes in the United States and United Kingdom developing Arabic, Swahili, and Indic language coverage.
- Audio:Speech recordings, environmental soundscapes, and acoustic event detection samples for voice assistants and industrial monitoring.
- Video:Temporal annotation of action sequences, object tracking trajectories, and multimodal alignment for surveillance and entertainment applications.
- Sensor Data:LiDAR point clouds, radar streams, and IMU telemetry fused with camera feeds for autonomous system training.
Image dominates installed base. Text is where expansion concentrates.
Use Case:
Cost tiers separate commodity annotation from specialized domains requiring certified technicians and regulatory documentation.
- Natural Language Processing:Tokenized text corpora, instruction-following datasets, and reinforcement learning from human feedback collections for conversational AI. Financial services firms in Singapore and the United Kingdom procure domain-specific linguistic datasets for compliance document analysis.
- Computer Vision:Object detection, semantic segmentation, and instance segmentation for manufacturing quality control and retail analytics. Tech startups in San Francisco and Seattle cluster procurement around hyperscaler cloud campuses.
- Speech Recognition:Transcribed audio, speaker identification, and accent variation datasets for voice interfaces.
- Predictive Analytics:Structured tabular data, time-series sequences, and feature-engineered datasets for forecasting and recommendation systems.
- Autonomous Systems:Multi-modal sensor fusion datasets combining perception, prediction, and planning annotations for robotics and self-driving vehicles.
Computer Vision anchors current revenue. Natural Language Processing is climbing the fastest.
End User:
Customer type determines contract structure, with automotive OEMs demanding sovereign cloud configurations and audit trails while tech startups favor API-accessible annotation platforms.
- Tech Startups:Venture-backed companies procuring pre-labeled datasets through platform APIs and crowd-sourced marketplaces to accelerate model development timelines.
- Research Institutes:Academic and government laboratories assembling open-source corpora and benchmarking datasets with emphasis on reproducibility and bias documentation.
- Automotive OEMs:German and Japanese manufacturers requiring EU-local annotation centers with chain-of-custody capabilities for NHTSA and KBA compliance.
- Financial Services Firms:Banks and insurers sourcing linguistic datasets for document understanding and computer vision pipelines for fraud detection.
- E-commerce Companies:Retail platforms procuring product image annotation and recommendation training data at scale.
Automotive OEMs drive premium pricing. Tech Startups represent the steepest expansion trajectory.
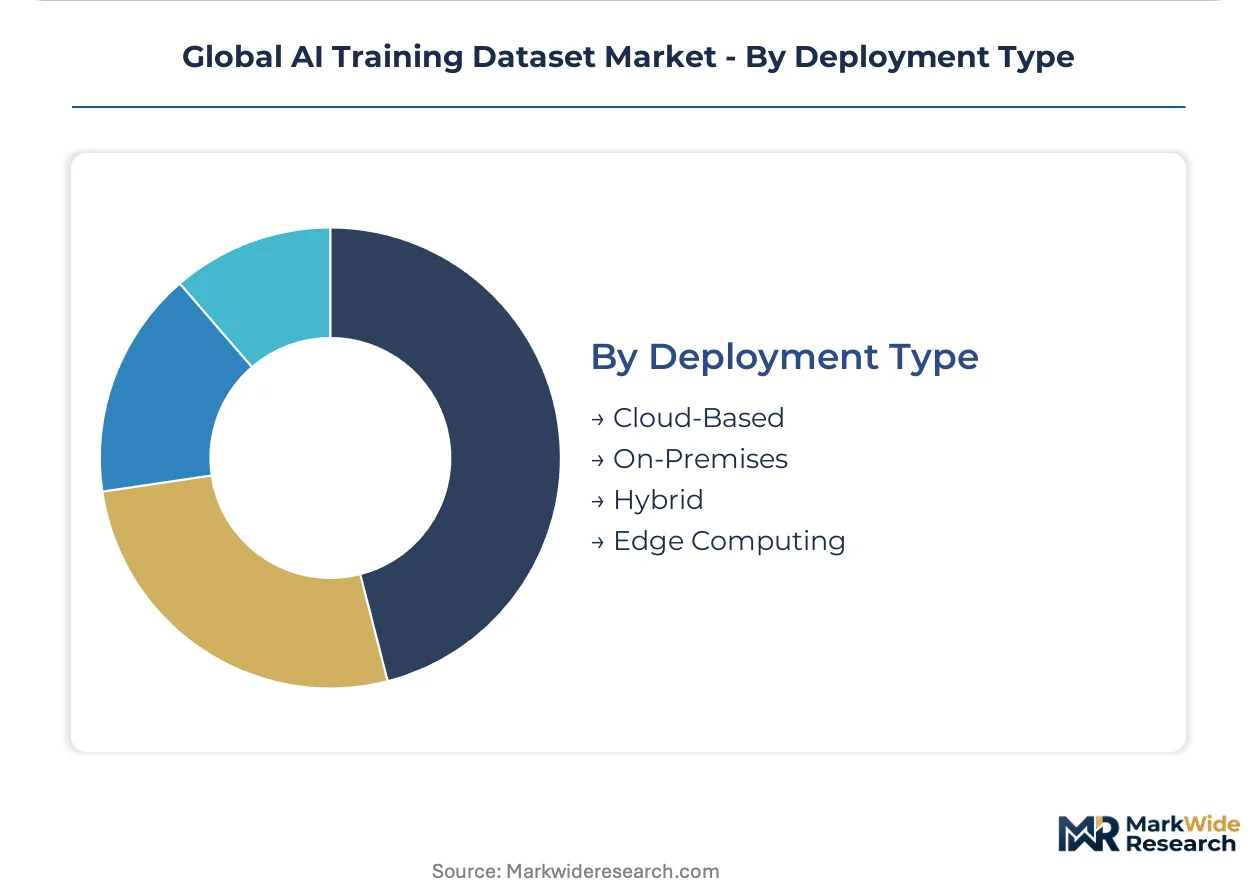
Deployment Type:
Volume concentration favors cloud-based configurations, though edge computing gains traction where data sovereignty and latency constraints apply.
- Cloud-Based:Centralized annotation platforms, synthetic data generation pipelines, and distributed workforce coordination through web interfaces. Absorbs majority of new spending as hyperscalers expand San Francisco and Seattle campuses.
- On-Premises:Air-gapped installations for classified government contracts and financial institutions with strict data residency requirements.
- Hybrid:Split configurations processing sensitive raw data locally while outsourcing annotation labor to distributed cloud workforces.
- Edge Computing:Federated learning architectures enabling automotive OEMs in France and South Korea to train models on distributed fleet data without centralizing sensor streams.
Cloud-Based holds installed base dominance. Edge Computing is gaining share fastest.
Need this report tailored to your region?
Request specific countries, segments, or companies — tailored to your requirements.
Regional Outlook
Consumption patterns diverge sharply across geographies. The United States prioritizes frontier model training at hyperscaler scale, while Germany and Japan concentrate procurement on regulatory-compliant automotive sensor datasets. China and India pursue divergent localization strategies under data sovereignty mandates.
United States
Venture-backed annotation startups cluster around San Francisco and Seattle to serve hyperscaler cloud campuses. The FDA regulates machine learning-enabled medical devices, compelling dataset provenance documentation for radiology AI developers. Scale AI anchors the frontier model data pipeline through its RLHF contractor network and government contracts.
Germany
Automotive OEMs in Bavaria and Baden-Württemberg procure multi-modal LiDAR and camera datasets for urban navigation training. The KBA mandates dataset reporting for autonomous vehicle safety assessments alongside EU AI Act risk-classification compliance. Stuttgart-based suppliers operate EU-local annotation centers with chain-of-custody capabilities.
Japan
Manufacturing quality control and robotics perception drive demand for precision-labeled industrial imagery. METI guidelines emphasize data governance frameworks for AI training corpora in sensitive sectors. Tokyo-Osaka industrial corridors host specialized 3D point cloud annotation facilities serving automotive and machinery exporters.
China
Domestic hyperscalers assemble training datasets under MIIT data localization requirements and SAMR algorithmic governance rules. The Yangtze River Delta and Pearl River Delta concentrate synthetic data generation capacity for computer vision model development. Cross-border transfer restrictions force redundant infrastructure deployment versus global dataset assembly.
India
Bengaluru and Hyderabad emerge as annotation labor hubs for multilingual NLP corpora and computer vision pipelines. The DPDP Act mandates granular consent management for biometric datasets, creating compliance-as-a-service revenue streams. IT services exporters leverage English-proficient workforces to capture offshore annotation contracts from North American and European buyers.
Global AI Training Dataset Market Competitive Landscape
Capability concentration sits with specialized annotation boutiques; scale advantage sits with hyperscaler-aligned pipeline orchestrators. The vendor base stratifies across three tiers: frontier model data contractors with government security clearances, enterprise crowd-sourcing platforms with linguist networks spanning 170 countries, and intellectual property marketplaces licensing proprietary speech and NLP datasets. Dominant competitive moves include M&A to acquire certified medical imaging annotation teams and strategic partnerships to embed compliance documentation into healthcare and automotive supplier contracts.
Within the frontier model contractor tier, Scale AI exemplifies hyperscaler-aligned scale advantages through its RLHF specialist recruitment and federal procurement relationships. Appen occupies a position representing enterprise crowd-sourcing archetypes with distributed workforce coordination across linguistic domains. Defined.ai anchors the intellectual property marketplace segment, licensing curated datasets to European telecom and banking clients under GDPR and EU AI Act documentation requirements. These three patterns—government-secured scale, enterprise crowd elasticity, and proprietary dataset licensing—capture the competitive structure compressing margins at raw collection tiers while concentrating pricing power upstream.
| Leading Market Players |
|---|
| Cogito Tech |
| Twine AI |
| Appen |
| Shaip |
| Nexdata |
| Scale AI |
| iMerit |
| Defined.ai |
| TELUS International |
| Others |
Supply & Pricing Matrix
Annotation labor pools concentrated in India and the Philippines feed directly into margin compression at the collection tier, while synthetic data generation and compliance documentation layers capture value upstream in Germany and the United States.
Pricing Analysis
Long-term offtake contracts dominate procurement between automotive OEMs and specialized annotation boutiques, locking in quarterly refresh rates for LiDAR and camera datasets. Three-tier pricing structure across premium, standard, and economy levels separates FDA-validated medical imaging annotation from crowd-sourced retail analytics labeling. Pricing pressure stems from synthetic data generation pipelines reducing physical capture costs for rare edge cases. Tech startups exhibit highest price sensitivity, while German automotive manufacturers absorb premium rates for EU-local annotation centers with KBA-compliant audit trails.
Supply Chain Analysis
Export-control regimes limiting GPU and cloud infrastructure flows to Chinese hyperscalers fragment global dataset assembly, forcing redundant annotation center deployment. Supply concentration centers on the United States for frontier model training infrastructure, Germany for automotive sensor data compliance, and India for multilingual NLP labor arbitrage. Raw material dependencies span certified medical imaging technicians, RLHF specialist contractors, and neural rendering compute capacity. Single-source vulnerability sits with Scale AI's federal security clearance network for government contracts. Distribution runs through direct hyperscaler partnerships, specialized boutique relationships, and open-source community contributions.
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Analyst Recommendations
Buyer power is concentrating among hyperscaler cloud campuses and automotive OEMs with sovereign cloud requirements, fragmenting procurement relationships away from full-service vendors toward specialized tier-1 and tier-2 suppliers.
For Market Incumbents: Pre-empt synthetic data substitution by acquiring neural rendering engineering teams in the United Kingdom and Israel, and embed EU AI Act documentation capabilities into healthcare supplier contracts before the EMA hardens technical specifications. Scale AI's government contracting network represents a replicable moat requiring security clearance investment.
For New Entrants and Emerging Players: Build out low-resource language coverage in Arabic, Swahili, and Indic languages through academic consortium partnerships in Nairobi and Bengaluru, where penetration remains shallow. Target federated learning architectures for South Korean automotive OEMs requiring localized fleet validation without centralizing sensor streams.
For Investors and Strategic Acquirers: Secondary-cycle assets sit with PE-backed annotation platforms holding 170-country linguist networks but lacking synthetic generation capabilities. Five-to-ten year viability hinges on backward integration into neural rendering or compliance-as-a-service revenue streams. Watch for FDA guidance on machine learning-enabled medical devices as an inflection signal for radiology AI dataset demand.
| Strategic Initiative | Industry Significance |
|---|---|
| Acquisition of Specialist Firm | Certified medical imaging annotation teams in Germany command scarcity premiums from radiology AI developers. |
| Strategic Partnership | Sovereign cloud alliances with French automotive OEMs enable federated learning without GDPR cross-border exposure. |
| Geographic Expansion | EU-local annotation centers satisfy KBA and EU AI Act chain-of-custody mandates for Bavarian OEM procurement. |
| Platform Integration | Neural rendering engines embedded into continuous validation loops reduce marginal cost of autonomous vehicle edge cases. |
| Product Launch | Compliance-as-a-service offerings address India's DPDP Act biometric consent requirements for voice dataset providers. |
Research Methodology
The analysis maps image annotation pipelines, text corpus assembly, synthetic data generation, and regulatory compliance services, each validated through CTOs at frontier model labs, procurement leads at German automotive OEMs, compliance officers at European healthcare AI developers, and workforce coordinators at Indian annotation hubs. Primary interview insights triangulated against SEC filings from publicly traded data providers, hyperscaler capex disclosures, FDA 510(k) submission databases, EU AI Act implementation guidance, and customs records for cross-border data transfer volumes. Bottom-up segment sizing and top-down market reconciliation anchored quantitative outputs.
Assumption sets held regulatory enforcement timelines and synthetic data substitution rates fixed while varying autonomous vehicle deployment pace and multilingual LLM research funding across the projection horizon. Segmentation dimensions modeled include data type, use case, end user, and deployment configuration. CAGRs derived from fitted growth curves against historical procurement patterns and disclosed contract values. Forecast inputs incorporated RLHF specialist wage inflation and GPU compute cost trajectories.
Stress conditions across EU AI Act documentation mandate timing, India DPDP Act enforcement intensity, and US FDA medical device guidance pace were modeled; outcomes outside those bands fall beyond the analytical envelope. Forecasts reflect these bounded assumptions and acknowledge that regulatory fragmentation or breakthrough synthetic generation quality could materially revise trajectory. Continuous validation against operating reality is the recommended discipline.
Need Custom Data?
Can't find what you're looking for? Our analysts can build a custom report tailored to your exact requirements.
1,000+
Global Clients
150+
Countries Covered
65,000+
Reports Available
Frequently Asked Questions
Why Work With MWR
Trusted by 1,000+ businesses across 150+ countries for high-stakes market decisions.
Ready to access intelligence that moves business?
Browse Reports →Trusted by Global Leaders
From Fortune-level organizations to global SMEs, we provide intelligence for high-stakes decisions.
Multi-Language Support
Research available in French, German, Spanish, Chinese, and more.
ISO & IAF Certified
Globally aligned quality standards ensuring methodological discipline and data integrity.
Competitive Relevance
Free inclusion of 3–4 additional companies of your choice in every report.
Customized Insights
Tailored intelligence for market entry, niche expansion, or competitive benchmarking.
Post-Sale Assistance
Dedicated coordination to help interpret findings and address queries post-delivery.
Cutting-Edge Methods
Structured data collection, advanced analytics, and expert validation for reliable forecasts.
Value for Investment
Credible, structured intelligence at a cost that makes strategic sense.
What Our Clients Say
My team needed the real numbers on AI spending for our Reinvention Services work. MarkWide delivered. No fluff, just a clear look at where the money is actually going. It saved us about three weeks of guesswork.
Accenture
We recently leaned on MarkWide Research for a deep dive into the evolving snacking habits within Southeast Asia. Their report on the premium biscuit segment was exceptionally detailed, providing us with the specific consumer sentiment data we needed to refine our regional flavor strategy. It wasn't just a data dump; the cultural nuances they captured helped us avoid several localization pitfalls.
Mondelez
Director of Global Consumer Insights
For a recent engagement in the automotive sector, we needed rigorous, independent verification of EV battery recycling capacities. MWR delivered a report that made our work easier. Their ability to segment the competitive landscape by chemical composition and regional throughput was exactly the kind of 'hard-to-find' intel that our team was looking for.
BCG
We were looking for a report on Xcelerator ecosystem's potential and got in touch with MarkWide's team through one of my old colleagues who worked with them in the past. Their research team was incredibly polite and were always available for us which was important for my team as this was a custom project. Their methodology for tracking industrial IoT adoption gave our R&D heads the clarity needed to prioritize our next-gen sensor development.
Siemens
Head of Industrial Digitalization
During a recent M&A project, we needed a fast, reliable breakdown of the Fintech landscape in Southeast Asia. MarkWide came through with a report that was actually readable and focused on the metrics that matter. It saved my team a good week of primary research, which, given our timelines, was a massive win.
KPMG
Advisory Partner
We tapped MarkWide Research for a deep dive into the ESG reporting software market. At Deloitte, our clients expect us to have the most current insights, and this report didn't disappoint. It provided a breakdown of the competitive field that was far more detailed than what we were expecting.
Deloitte
Lead Consultant, Sustainability Services
For our semiconductor division at Samsung, the supply chain forecast from MarkWide was incredibly useful. It provided a realistic outlook on raw material availability that helped us refine our production timelines. No fluff, just the data we needed to make a tough call.
Samsung
The value for our organization comes from three things: depth of research, specificity of segments and being easy to work with. As important as the first two are, the third can't be underestimated. MarkWide Research, maybe more than any other research vendor, wants to know what is top of mind for our team and what big questions we are grappling to answer. Their customer first approach and high value engagement model have given us great analysis and excellent value for money.
3M
I can share that it was a positive experience wherein MarkWide Research demonstrated flexibility to adapt to our needs and delivered an excellent report that fits all our requirements. Personally, I liked the timely follow up by the team and we will definitively reach out in case more research support is required.
VITO
Related Reports
Artificial Intelligence (AI)
Emotion Detection and Recognition (EDR) Market
Artificial Intelligence (AI)
AI Demand Forecasting Software Market
Artificial Intelligence (AI)
AI Image Recognition Market
Artificial Intelligence (AI)
No-Code AI Platform Market
Artificial Intelligence (AI)
AI in Food & Beverages Market
Artificial Intelligence (AI)
Global Artificial Intelligence in Law Market
Artificial Intelligence (AI)
NLP in Healthcare and Life Sciences Market
Artificial Intelligence (AI)
Adaptive AI Market
Artificial Intelligence (AI)
Synthetic Data Generation Market
Artificial Intelligence (AI)
Home AI Oven Market
Artificial Intelligence (AI)
Natural Language Processing in BFSI Market
Artificial Intelligence (AI)
Machine Learning As a Service (Mlaas) Market
Artificial Intelligence (AI)
Global Artificial Intelligence (AI) in Food and Beverages Market
Artificial Intelligence (AI)
Global Computer Assisted Coding Market
Artificial Intelligence (AI)
Artificial Intelligence (AI) in Manufacturing Market
Artificial Intelligence (AI)
Global Artificial Intelligence in Life Science Market