
 Apache Spark Market | 2026-2036
Apache Spark Market Size, Share, and Industry Trends Forecast 2026-2036
Apache Spark Market Analysis
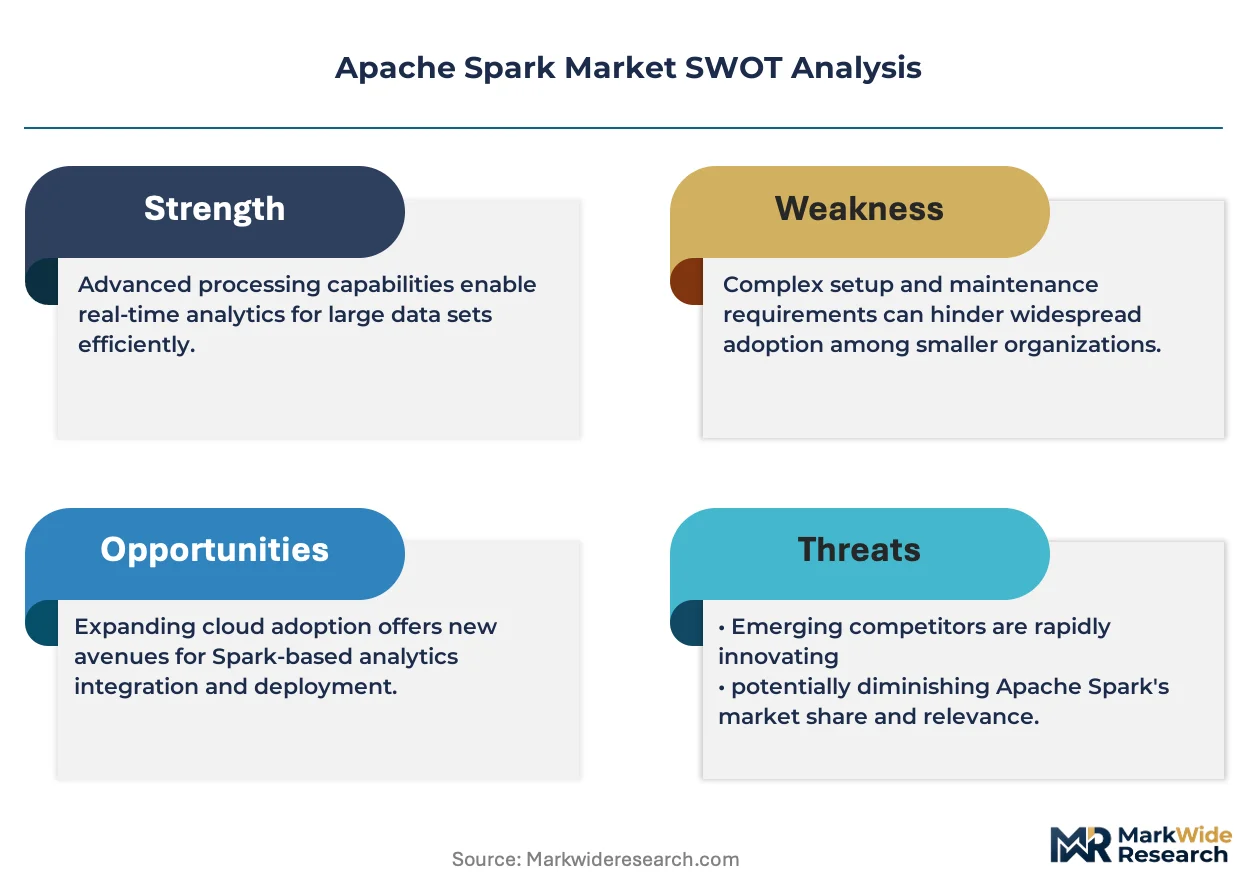
ISO 27001 certification cycles for cloud data platforms is unwinding competitive access across enterprise procurement. Databricks leverages its unified analytics platform to anchor commercial Spark distribution. Amazon sustains managed service dominance through EMR and Glue integrations. Capital One differentiates via in-house Spark optimization for credit-risk modeling.
Apache Spark is an open-source unified analytics engine for large-scale data processing, executing in-memory computations up to 100 times faster than Hadoop MapReduce for iterative algorithms. Its primary purpose centers on accelerating batch processing, SQL queries, stream processing, and machine learning workloads across distributed clusters. Public cloud deployment captures the largest revenue pool as enterprises exit owned data centers, while machine learning applications within the application area dimension expand fastest due to MLOps pipeline integration. Streaming data segments command premium pricing from telecommunications and finance verticals requiring sub-second latency.
FCC guidelines on data privacy in telecommunications intersect with HIPAA requirements for healthcare analytics platforms, creating compliance complexity for cross-industry Spark deployments. The EU AI Act imposes risk-classification obligations on automated decision systems built atop Spark machine learning pipelines. Enterprises must evaluate whether managed service providers or self-managed clusters deliver superior audit trail integrity before scaling production workloads.
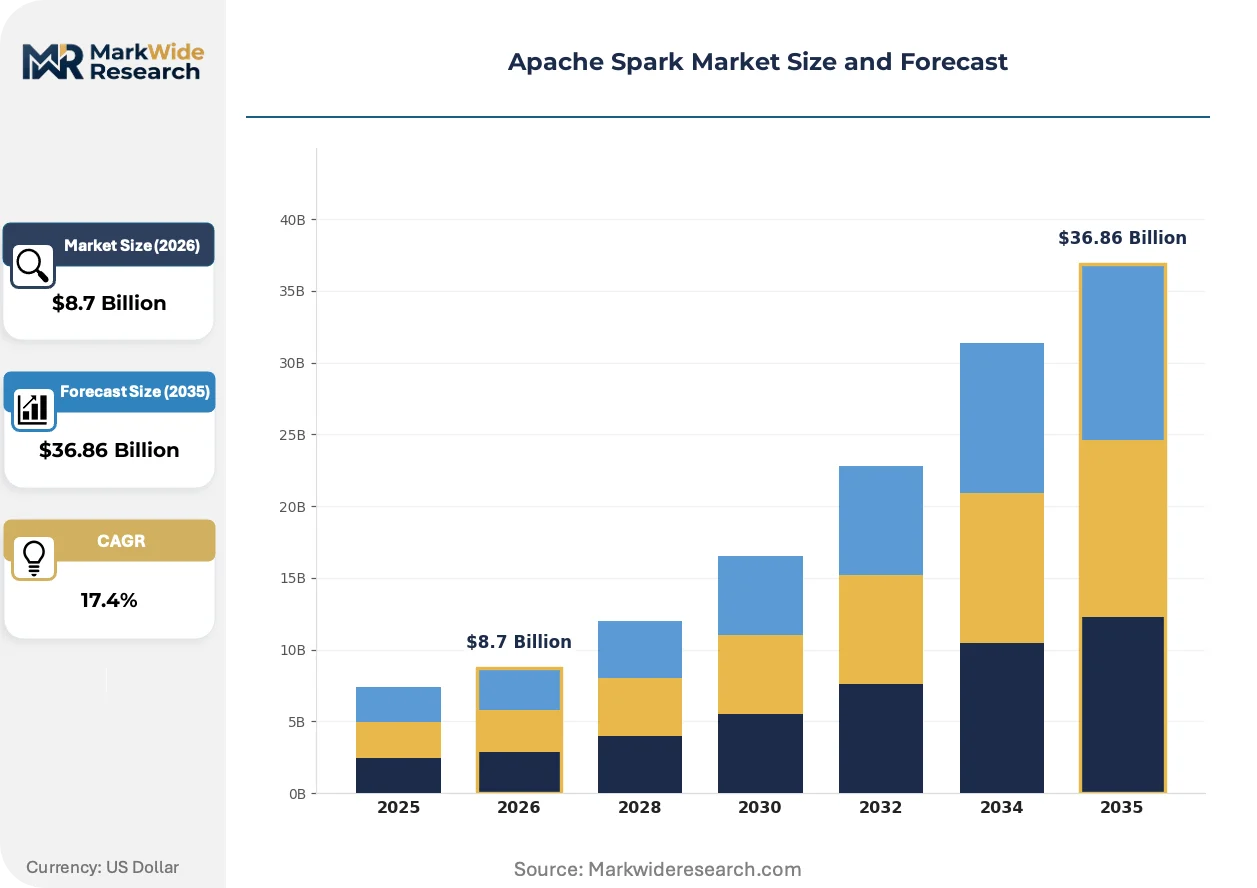
Market Dynamics
The EU AI Act's risk-classification obligations for automated decision systems are forcing enterprises to rearchitect Spark machine learning pipelines for auditability, creating immediate procurement pressure for compliant managed service configurations.
Growth Catalysts
- GDPR-mandated data residency:Cloud migration requirements under European data protection law accelerate enterprise upgrades to managed Spark distributions with built-in governance controls.
- Real-time fraud detection:Financial services firms deploy Spark streaming for sub-second transaction scoring, driving consumption in quantitative trading and payment processing infrastructure.
- In-memory computation speed:Spark's 100x performance advantage over Hadoop MapReduce for iterative algorithms pulls batch workloads from legacy data warehouses.
Market Restraints
- Specialized talent scarcity:Shortage of Scala and PySpark engineers constrains cluster optimization and pipeline development timelines.
- Cloud vendor lock-in:Proprietary optimizations in Amazon EMR and Databricks runtime create migration friction for multi-cloud strategies.
- Memory cost volatility:DRAM price fluctuations directly impact total cost of ownership for in-memory computing clusters.
Strategic Opportunities
- Healthcare analytics expansion:HIPAA-compliant Spark deployments for clinical genomics and population health management remain underpenetrated relative to financial services adoption.
- ISO 27001 certification differentiation:Independent security validation creates procurement advantage for managed service providers in regulated industries.
- Edge-to-cloud streaming convergence:Integration of Apache Spark with 5G network edge nodes enables new low-latency use cases in telecommunications.
Industry Challenges
- Legacy system integration:Mainframe and on-premise data warehouse connectivity requires custom connector development and extended validation cycles.
- Cross-regulatory compliance complexity:Simultaneous FCC telecommunications privacy rules and HIPAA healthcare requirements create conflicting architectural demands for multi-industry deployments.
Report Scope
MarkWide Research| Attributes | Details |
|---|---|
| Report Title | Apache Spark Market |
| Market Size in 2026 | $8.7 Billion |
| Market Size in 2035 | $36.86 Billion |
| CAGR (2026 – 2036) | 17.4% |
| Historical Year | 2020-2024 |
| Base Year | 2025 |
| Forecast Period | 2026-2036 |
| Segmentation | Deployment Model: On-Premises, Public Cloud, Private Cloud, Hybrid Cloud Application Area: Data Processing, Data Analytics, Machine Learning, Streaming Data Industry Vertical: Finance, Retail, Healthcare, Telecommunications End User: Data Scientists, Business Analysts, IT Administrators, Developers |
| Companies Covered | Databricks, Amazon, Capital One, JPMorgan Chase, Visa, Citi, Apple, Verizon, Pure Storage, Others |
| Regions Covered | North America: US, Canada, Mexico Europe: Germany, Italy, France, UK, Spain, Denmark, Sweden, Austria, Belgium, Finland, Turkey, Poland, Russia, Greece, Switzerland, Netherlands, Norway, Portugal, Rest of Europe Asia Pacific: China, Japan, India, South Korea, Indonesia, Malaysia, Kazakhstan, Taiwan, Vietnam, Thailand, Philippines, Singapore, Australia, New Zealand, Rest of Asia Pacific South America: Brazil, Argentina, Colombia, Chile, Peru, Rest of South America Middle East & Africa: Saudi Arabia, UAE, Qatar, South Africa, Israel, Kuwait, Oman, North Africa, West Africa, Rest of MEA |
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Apache Spark Market Emerging Trajectories
Spark's architecture is undergoing rapid specialization as enterprises demand tighter integration between streaming analytics, machine learning operations, and governed data sharing across organizational boundaries.
Structured streaming is supplanting micro-batch processing as the default paradigm for continuous data ingestion. Telecommunications operators and capital markets firms now mandate exactly-once processing semantics for network telemetry and order flow analytics. This shift is compressing acceptable latency windows from seconds to milliseconds and disqualifying legacy batch-oriented competitors.
The EU AI Act's automated decision system obligations are reshaping MLOps pipeline architecture. Enterprises must now embed explainability logging and human-in-the-loop checkpoints directly within Spark MLlib workflows. Healthcare and financial services verticals are responding fastest, with procurement committees requiring proof of risk-classification compliance before production deployment authorization.
Consumption-based pricing models are displacing reserved instance commitments for Spark workloads. Retail and logistics buyers now favor serverless autoscaling configurations over provisioned clusters, particularly for seasonal demand spikes. This behavioral shift is most visible in United States enterprise procurement, where finance teams prioritize operational expenditure classification over capital-intensive infrastructure ownership.
Apache Spark Market Segmentation
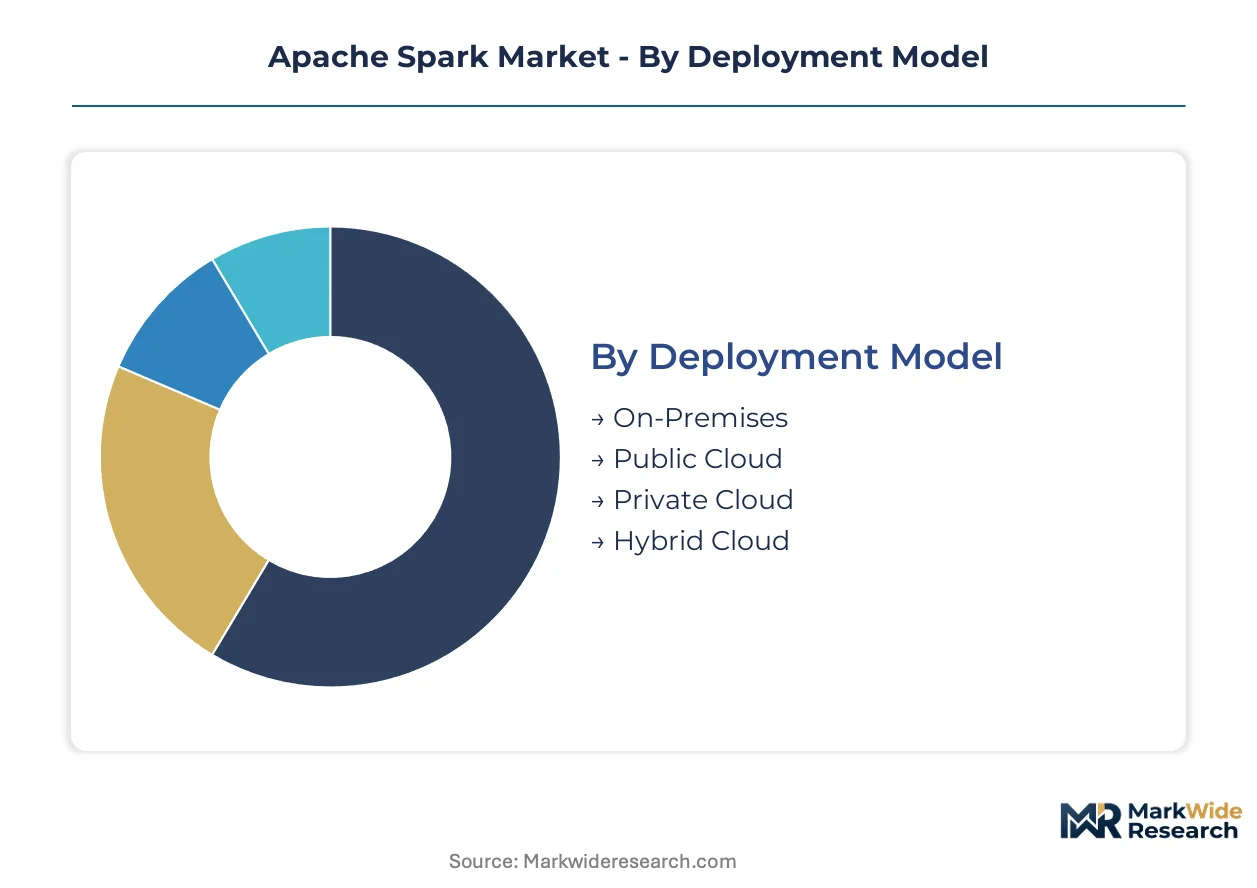
Apache Spark deployments fragment across infrastructure strategies, analytical workloads, and practitioner skill levels. Procurement committees evaluate segments against GDPR data residency mandates, HIPAA audit trail requirements, and EU AI Act risk-classification obligations. Each dimension carries distinct compliance implications that reshape vendor selection and architectural design.
Deployment Model:
GDPR-mandated data residency in Frankfurt and Paris data centers drives divergent infrastructure commitments across European financial institutions.
- On-Premises:Enterprises maintain physical control over hardware clusters to satisfy HIPAA audit trail requirements for healthcare analytics. Capital One and regulated banks in Frankfurt favor this model for credit-risk workloads where data sovereignty overrides cloud agility.
- Public Cloud:Amazon EMR and Databricks runtime dominate procurement in United States quantitative trading desks seeking sub-second autoscaling. Consumption-based pricing displaces reserved instances as finance teams prioritize operational expenditure classification.
- Private Cloud:Single-tenant virtualized environments serve telecommunications operators in Germany navigating FCC-equivalent national privacy regulations alongside GDPR obligations.
- Hybrid Cloud:Burst capacity configurations link on-premise historical data lakes with cloud-based streaming analytics for seasonal retail demand spikes.
Established volume favors Public Cloud; emerging adoption favors Hybrid Cloud.
Application Area:
Latency requirements separate batch-oriented workloads from continuous processing pipelines in capital markets infrastructure.
- Data Processing:ETL pipelines migrate from Hadoop MapReduce to Spark SQL for 100x acceleration on iterative algorithms. United States logistics clusters deploy these configurations for supply chain optimization.
- Data Analytics:Interactive dashboards leverage Spark SQL and DataFrames for ad-hoc exploration across petabyte-scale datasets. Business analysts in London and Singapore drive demand for governed data sharing interfaces.
- Machine Learning:MLOps pipeline integration expands fastest as EU AI Act obligations force explainability logging and human-in-theoop checkpoints within MLlib workflows. Healthcare verticals in Switzerland and France mandate risk-classification compliance before production authorization.
- Streaming Data:Exactly-once processing semantics satisfy telecommunications operators in Tokyo and New York monitoring 5G network telemetry with millisecond latency requirements.
Legacy dominance stabilizes Data Processing; steepest expansion trajectory belongs to Machine Learning.
Industry Vertical:
Compliance complexity varies sharply between single-regulator environments and cross-industry deployments facing overlapping mandates.
- Finance:Real-time fraud detection pipelines in quantitative trading desks and payment processors command premium pricing for sub-second transaction scoring. United States and United Kingdom regulators impose granular audit requirements on automated decision systems.
- Retail:Seasonal demand forecasting and recommendation engines drive serverless autoscaling configurations. Procurement committees in France and Germany favor consumption-based models over capital-intensive cluster ownership.
- Healthcare:Clinical genomics and population health management remain underpenetrated relative to financial services adoption. HIPAA compliance complexity constrains vendor selection to ISO 27001-certified managed service providers.
- Telecommunications:FCC guidelines on data privacy intersect with GDPR requirements for cross-border traffic analysis, creating architectural tension for multinational operators.
Revenue concentration favors Finance; greenfield opportunity favors Healthcare.
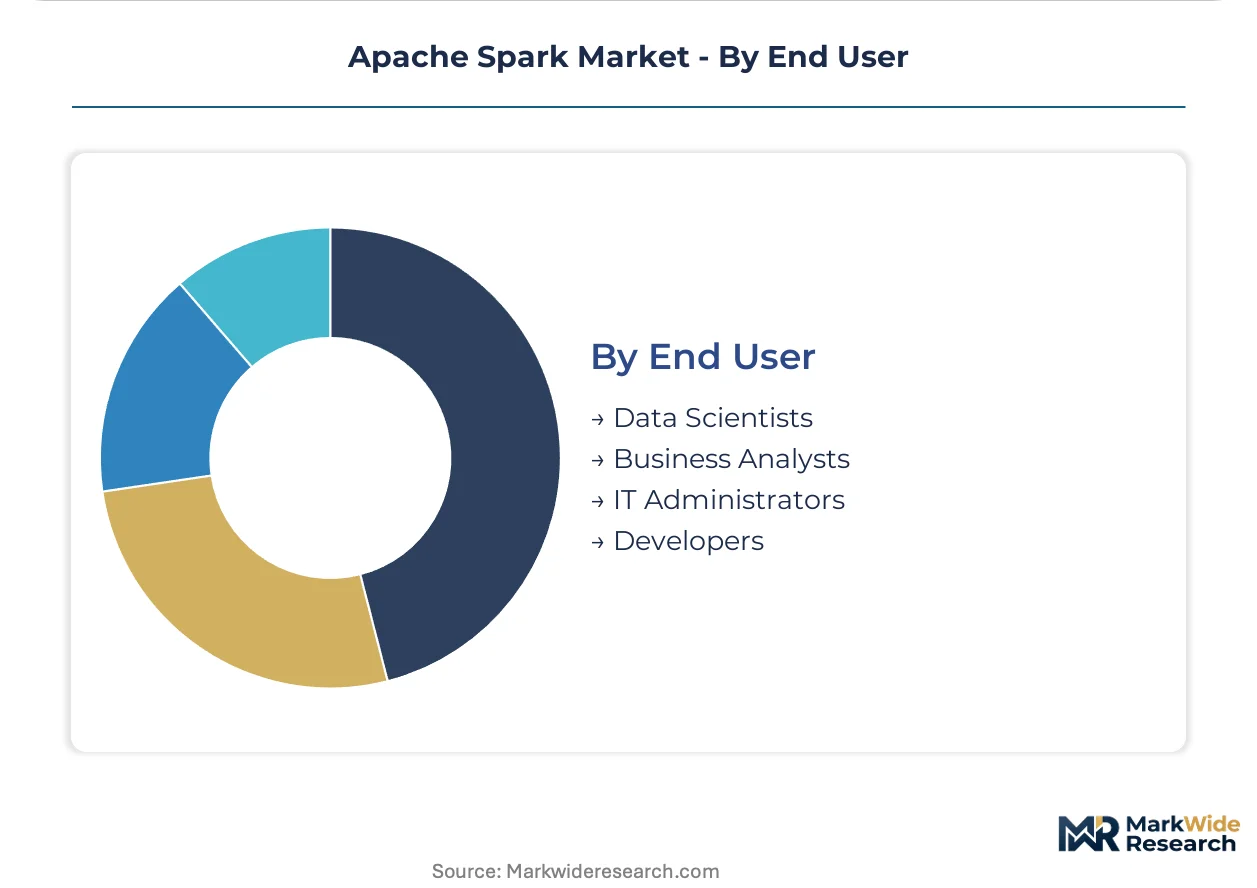
End User:
Skill scarcity shapes tooling investments and training budgets across practitioner categories.
- Data Scientists:PySpark and Scala proficiency gaps constrain pipeline development timelines at pharmaceutical companies in Basel and Boston. Managed notebook environments reduce infrastructure friction.
- Business Analysts:SQL-native interfaces through Spark SQL lower adoption barriers for finance and marketing teams in Chicago and Mumbai.
- IT Administrators:Cluster optimization and security configuration demand specialized talent scarce in secondary European markets.
- Developers:Streaming application builders in Tel Aviv and Bangalore integrate Structured Streaming APIs with microservices architectures.
Technical depth concentrates with Data Scientists; accessibility expansion targets Business Analysts.
Need this report tailored to your region?
Request specific countries, segments, or companies — tailored to your requirements.
Regional Outlook
EU AI Act risk-classification obligations and GDPR data residency mandates are reshaping procurement patterns across enterprise Spark deployments. Cloud migration incentives in Frankfurt and Paris accelerate managed service adoption. Hyperscale data center investments in Virginia and Tokyo concentrate real-time analytics capacity.
United States
Quantitative trading desks in Manhattan and Chicago drive sub-second latency requirements for fraud detection pipelines. SEC audit trail obligations force explainability logging within automated decision systems. Northern Virginia hyperscale clusters anchor the largest consumption volumes for streaming analytics infrastructure.
Germany
Telecommunications operators in Frankfurt and Munich navigate GDPR-equivalent national privacy regulations alongside EU AI Act compliance. The country's federal data protection authority enforces granular consent requirements for cross-border data flows. Bavarian automotive clusters deploy Spark for supply chain optimization with embedded governance controls.
United Kingdom
Financial services firms in London's Square Mile prioritize ISO 27001-certified managed services for credit-risk modeling workloads. The Financial Conduct Authority imposes operational resilience requirements on real-time transaction processing systems. Edinburgh and Manchester data centers capture secondary demand from insurance analytics providers.
Japan
METI industrial digitization programs subsidize Spark adoption for manufacturing quality control and predictive maintenance. Tokyo and Osaka financial exchanges mandate exactly-once processing semantics for order flow analytics. Nagoya automotive suppliers integrate streaming analytics with production line robotics.
India
SEBI's market infrastructure regulations drive real-time surveillance system upgrades at Mumbai and Bangalore exchanges. The country's central bank mandates data localization for payment processing analytics. Hyderabad and Pune technology campuses host the largest PySpark engineering talent pools outside North America.
Apache Spark Market Vendor Landscape
Listed leaders compete with private specialists across managed service and self-managed distribution channels. The vendor base concentrates around three strategic archetypes: unified analytics platforms, hyperscale cloud integrators, and in-house financial services optimizers. Consolidation pressure intensifies as ISO 27001 certification cycles filter procurement shortlists. Dominant competitive moves include strategic partnerships for compliance tooling and geographic expansion into GDPR-mandated European data centers.
Within the unified analytics tier, Databricks anchors commercial Spark distribution through managed notebook environments and governance interfaces. Amazon exemplifies hyperscale cloud integration via EMR and Glue service bundles. Capital One occupies a distinctive position as an in-house optimizer, representing financial services firms that bypass external vendors for sensitive credit-risk workloads.
| Leading Market Players |
|---|
| Databricks |
| Amazon |
| Capital One |
| JPMorgan Chase |
| Visa |
| Citi |
| Apple |
| Verizon |
| Pure Storage |
| Others |
Supply Flow & Price Mechanics
Hyperscale data center utilization rates in Northern Virginia and Frankfurt establish the cost floor for managed Spark services, concentrating pricing power among cloud operators with captive infrastructure while forcing smaller providers toward niche certification premiums. This scale asymmetry feeds directly into procurement committee decisions across financial services and healthcare verticals.
Pricing Analysis
Certification level creates the primary spread between ISO 27001-validated managed services and uncertified self-managed deployments. Three-tier pricing structure across premium, standard, and economy levels reflects differentiation by audit trail granularity, with HIPAA-compliant configurations commanding substantial premiums over baseline GDPR-aligned offerings. Pricing pressure stems from serverless autoscaling commoditization as retail buyers prioritize consumption-based models over reserved instances. Mid-market enterprises exhibit highest price sensitivity, while quantitative trading desks demonstrate lowest elasticity due to latency requirements.
Supply Chain Analysis
United States and Germany anchor commercial Spark distribution through Databricks runtime development and Amazon EMR service infrastructure. DRAM supply from South Korea and Taiwan feeds into in-memory cluster hardware, while specialized Scala and PySpark engineering talent concentrates in India and Israel. Single-source vulnerability around hyperscaler-managed service APIs creates migration friction for multi-cloud strategies. Distribution runs through direct enterprise sales with embedded professional services and channel partner configurations for mid-market penetration.
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Analyst Recommendations
Apache Spark incumbents face substitution pressure from vector database architectures and specialized real-time streaming engines that bypass general-purpose distributed computing frameworks.
For Market Incumbents: Fortify governance interface differentiation by embedding EU AI Act risk-classification tooling directly within MLlib workflows. Pursue backward integration into edge computing hardware partnerships to capture 5G telecommunications workloads before cloud-native competitors consolidate this segment.
For New Entrants and Emerging Players: ISO 27001 fast-track certification enables procurement access to healthcare analytics verticals where HIPAA compliance complexity constrains incumbent expansion. Target clinical genomics and population health management applications in Switzerland and France, positioning against Databricks through specialized genomic data governance interfaces.
For Investors and Strategic Acquirers: Mid-cycle technology positioning favors managed service providers with embedded MLOps tooling over pure infrastructure plays. Long-term viability hinges on explainability logging capabilities as regulatory audit requirements harden across automated decision systems. Monitor SEBI and SEC enforcement patterns on real-time surveillance system procurement as inflection indicators for financial services demand.
| Strategic Initiative | Industry Significance |
|---|---|
| Platform Integration | Unified analytics interfaces reduce PySpark talent friction for pharmaceutical companies in Basel. |
| Strategic Partnership | Edge-to-cloud streaming alliances with 5G operators unlock telecommunications latency requirements. |
| Geographic Expansion | Frankfurt and Paris data center presence satisfies GDPR-mandated residency for European financial institutions. |
| Acquisition of Specialist Firm | Clinical genomics workflow tooling addresses underpenetrated healthcare vertical relative to finance. |
| Product Launch | Serverless autoscaling configurations align with retail procurement shifts toward operational expenditure classification. |
Methodological Framework
Cross-validation between primary interviews with data platform architects and secondary validation through hyperscaler capex disclosures anchors the qualitative findings. This study conducted structured discussions with CTOs, IT procurement officers, platform engineers, and integration specialists across financial services, healthcare, and telecommunications verticals. Secondary sources include SEC 10-K filings, EU regulatory filings under GDPR and EU AI Act, cloud infrastructure spending reports, and hospital procurement databases. Bottom-up cluster deployment estimates triangulate against top-down market sizing from managed service provider revenue disclosures.
Sensitivity analysis around DRAM price volatility and cloud migration velocity shapes the analytical framework across the projection horizon. Segmentation dimensions modeled include deployment model, application area, industry vertical, and end-user skill level, with regional regulatory cluster as an additional cross-cutting dimension. CAGRs derive from iterative convergence between historical consumption patterns and forward procurement pipeline visibility, incorporating MLOps pipeline integration rates and streaming workload expansion as industry-specific inputs.
Decision-makers should treat outputs as directional under assumptions of sustained GDPR enforcement and EU AI Act implementation timelines; material deviation in regulatory stringency or cloud cost structures would warrant model refresh. Recalibration cycles align with material shifts in hyperscaler pricing, memory commodity cycles, and cross-border data flow policy developments.
Need Custom Data?
Can't find what you're looking for? Our analysts can build a custom report tailored to your exact requirements.
1,000+
Global Clients
150+
Countries Covered
65,000+
Reports Available
Frequently Asked Questions
Why Work With MWR
Trusted by 1,000+ businesses across 150+ countries for high-stakes market decisions.
Ready to access intelligence that moves business?
Browse Reports →Trusted by Global Leaders
From Fortune-level organizations to global SMEs, we provide intelligence for high-stakes decisions.
Multi-Language Support
Research available in French, German, Spanish, Chinese, and more.
ISO & IAF Certified
Globally aligned quality standards ensuring methodological discipline and data integrity.
Competitive Relevance
Free inclusion of 3–4 additional companies of your choice in every report.
Customized Insights
Tailored intelligence for market entry, niche expansion, or competitive benchmarking.
Post-Sale Assistance
Dedicated coordination to help interpret findings and address queries post-delivery.
Cutting-Edge Methods
Structured data collection, advanced analytics, and expert validation for reliable forecasts.
Value for Investment
Credible, structured intelligence at a cost that makes strategic sense.
What Our Clients Say
My team needed the real numbers on AI spending for our Reinvention Services work. MarkWide delivered. No fluff, just a clear look at where the money is actually going. It saved us about three weeks of guesswork.
Accenture
We recently leaned on MarkWide Research for a deep dive into the evolving snacking habits within Southeast Asia. Their report on the premium biscuit segment was exceptionally detailed, providing us with the specific consumer sentiment data we needed to refine our regional flavor strategy. It wasn't just a data dump; the cultural nuances they captured helped us avoid several localization pitfalls.
Mondelez
Director of Global Consumer Insights
For a recent engagement in the automotive sector, we needed rigorous, independent verification of EV battery recycling capacities. MWR delivered a report that made our work easier. Their ability to segment the competitive landscape by chemical composition and regional throughput was exactly the kind of 'hard-to-find' intel that our team was looking for.
BCG
We were looking for a report on Xcelerator ecosystem's potential and got in touch with MarkWide's team through one of my old colleagues who worked with them in the past. Their research team was incredibly polite and were always available for us which was important for my team as this was a custom project. Their methodology for tracking industrial IoT adoption gave our R&D heads the clarity needed to prioritize our next-gen sensor development.
Siemens
Head of Industrial Digitalization
During a recent M&A project, we needed a fast, reliable breakdown of the Fintech landscape in Southeast Asia. MarkWide came through with a report that was actually readable and focused on the metrics that matter. It saved my team a good week of primary research, which, given our timelines, was a massive win.
KPMG
Advisory Partner
We tapped MarkWide Research for a deep dive into the ESG reporting software market. At Deloitte, our clients expect us to have the most current insights, and this report didn't disappoint. It provided a breakdown of the competitive field that was far more detailed than what we were expecting.
Deloitte
Lead Consultant, Sustainability Services
For our semiconductor division at Samsung, the supply chain forecast from MarkWide was incredibly useful. It provided a realistic outlook on raw material availability that helped us refine our production timelines. No fluff, just the data we needed to make a tough call.
Samsung
The value for our organization comes from three things: depth of research, specificity of segments and being easy to work with. As important as the first two are, the third can't be underestimated. MarkWide Research, maybe more than any other research vendor, wants to know what is top of mind for our team and what big questions we are grappling to answer. Their customer first approach and high value engagement model have given us great analysis and excellent value for money.
3M
I can share that it was a positive experience wherein MarkWide Research demonstrated flexibility to adapt to our needs and delivered an excellent report that fits all our requirements. Personally, I liked the timely follow up by the team and we will definitively reach out in case more research support is required.
VITO
Related Reports
Software & Services
Non-Profit Software Market
Software & Services
Middle East HR Payroll Software Market
Software & Services
Africa HR Payroll Software Market
Software & Services
Torque Software Market
Software & Services
Point Cloud Processing Software Market
Software & Services
Global PEO Software Market
Software & Services
Global Guidewire Market
Software & Services
Global Local SEO Software Market
Software & Services
Strategy Management Software Market
Software & Services
Global Calendar Scheduling Software Market
Software & Services
Software Market
Software & Services
Global App Store Optimization Tools Software Market
Software & Services
Software Release Management Tools Market
Software & Services
Multiexperience Development Platforms Market
Software & Services
Online Lottery Software Market
Software & Services
Global App Builder Software Market