
 AI Datasets Market | 2026-2036
AI Datasets Market Size, Share, and Industry Trends Forecast 2026-2036
AI Datasets Market Intelligence
The divergence in data annotation platform complexity and human-in-the-loop workforce scale is reorganizing the competitive landscape. Scale AI leads in providing sophisticated tooling for complex computer vision tasks required by autonomous systems. Appen leverages its extensive global crowd-based workforce for large-scale data labeling projects in consumer tech. Meanwhile, Databricks differentiates by integrating data lakehouse architecture with AI model development workflows, targeting enterprise data science teams.
AI datasets are structured collections of information, such as images or text, curated and annotated to train machine learning models. Annotation involves adding metadata, like labels or bounding boxes, to raw data to make it intelligible for algorithms. Image Data and Text Data represent the largest data type categories, directly supporting computer vision and Natural Language Processing applications. Significant demand originates from automotive OEMs developing autonomous systems and finance companies building fraud detection models.
Regulatory frameworks increasingly shape data sourcing and quality standards. The EU AI Act imposes stringent requirements on data used for high-risk AI, while in the United States, HIPAA governs the use of patient data. Vendor selection will increasingly depend on a provider’s ability to demonstrate auditable compliance with these disparate data governance and privacy mandates across key markets.
Market Dynamics
The AI Datasets market is defined by the tension between the explosive demand for massive data volumes, driven by complex models in sectors like autonomous driving, and the simultaneous rise of stringent data governance frameworks that mandate higher quality, privacy, and auditability.
Growth Catalysts
- Regulatory Mandates:The EU AI Act is compelling organizations to invest in high-quality, documented datasets for high-risk systems, creating a premium for providers who can demonstrate compliance and data provenance.
- Automotive Sector Demand:Autonomous vehicle development by automotive OEMs requires a constant feed of diverse, precisely annotated sensor data, including LiDAR, radar, and camera imagery, to train and validate perception models.
- Generative AI Expansion:The proliferation of Large Language Models and diffusion models for image generation necessitates vast, multimodal datasets for pre-training, representing a significant volume driver for both text and image data.
Market Restraints
- High Annotation Cost:The expense associated with manual data annotation, particularly for specialized tasks like 3D semantic segmentation for medical imaging or autonomous systems, remains a significant cost barrier for many organizations.
- Data Privacy Regulations:Frameworks such as GDPR in Europe and HIPAA in the United States severely restrict the collection and use of personal data, creating substantial hurdles for sourcing compliant training data for many applications.
- The Long-Tail Problem:The inherent difficulty in collecting sufficient data for rare edge cases leads to model brittleness and performance gaps, a fundamental technical restraint that standard data collection methods struggle to address.
Strategic Opportunities
- Synthetic Data Generation:Creating photorealistic, algorithmically generated data offers a pathway to bypass privacy constraints, fill gaps in real-world datasets, and safely model rare or dangerous scenarios for robust model training.
- Emerging Market Localization:There is a nascent opportunity for developing context-specific datasets for local languages and environments in technology hubs across India and Brazil, supporting the regional growth of NLP and computer vision applications.
- Data Provenance Services:As regulatory scrutiny intensifies, providing datasets with a transparent, auditable chain of custody for sourcing, consent, and annotation becomes a premium service and a key competitive differentiator.
Industry Challenges
- Domain-Specific Talent Scarcity:A shortage of data annotators and quality assurance personnel with deep expertise in specialized fields, such as radiology or agricultural science, creates bottlenecks and quality control issues.
- Lack of Standardization:The absence of universal standards for data formats, annotation schemas, and quality benchmarks creates interoperability friction, complicating the integration of datasets from different vendors and platforms.
- Complex Data Licensing:Navigating the intellectual property rights and licensing terms for large, aggregated datasets sourced from multiple origins presents a significant legal and operational hurdle for both providers and end-users.
Report Scope
MarkWide Research| Attributes | Details |
|---|---|
| Report Title | AI Datasets Market |
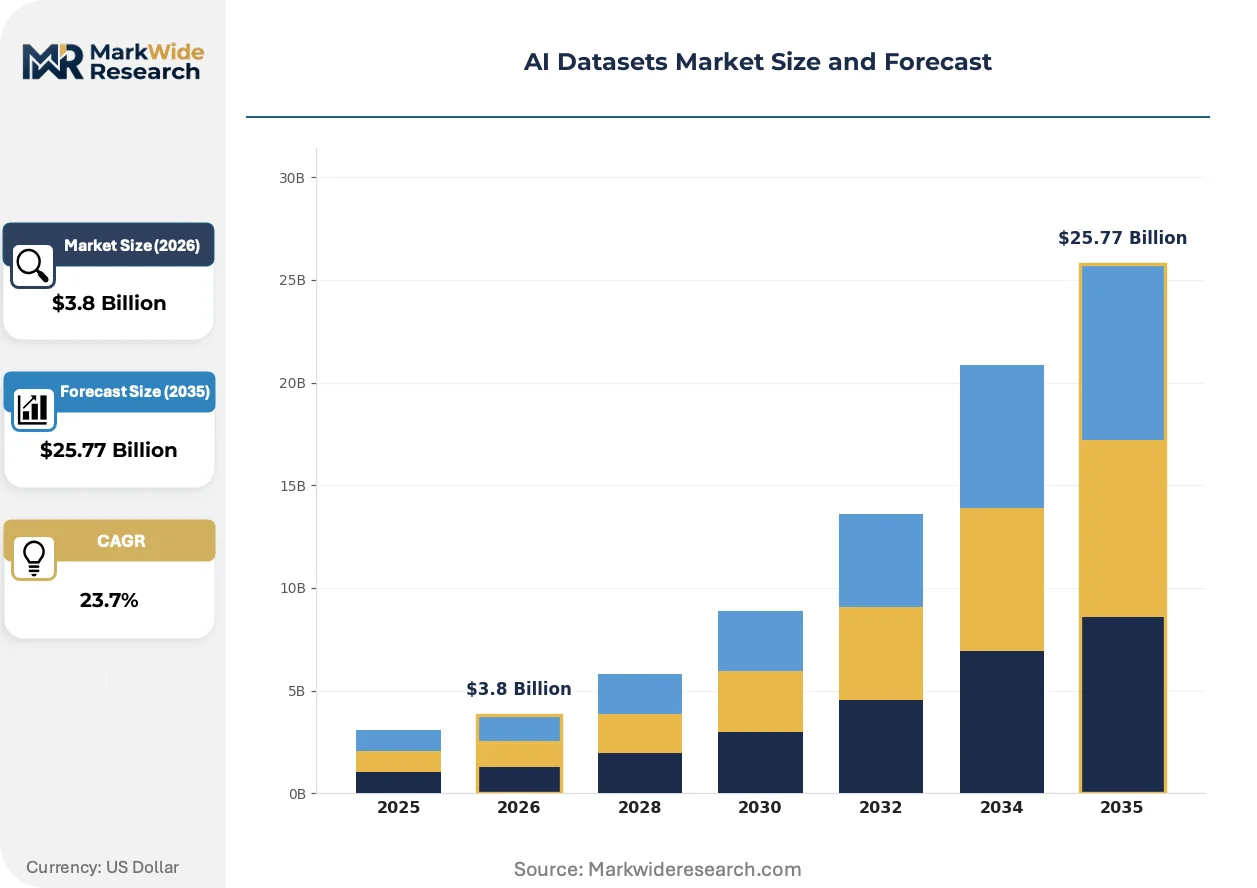
| Market Size in 2026 | $3.8 Billion |
| Market Size in 2035 | $25.77 Billion |
| CAGR (2026 – 2036) | 23.7% |
| Historical Year | 2020-2024 |
| Base Year | 2025 |
| Forecast Period | 2026-2036 |
| Segmentation | Data Type: Image Data, Text Data, Audio Data, Sensor Data, Video Data, Tabular Data Industry Vertical: Finance, Automotive OEMs, Telecommunications, Retail Chains, Agriculture, Manufacturing Plants Deployment Model: Public Cloud, Private Cloud, Hybrid Deployment, On-Premises, Edge Deployment, Multi-Cloud Use Case: Natural Language Processing, Predictive Maintenance, Computer Vision, Fraud Detection, Speech Recognition, Demand Forecasting |
| Companies Covered | TELUS International, Databricks, Scale AI, Snorkel AI, Labelbox, Appen, Cogito Tech, SuperAnnotate, iMerit, Others |
| Regions Covered | North America: US, Canada, Mexico Europe: Germany, Italy, France, UK, Spain, Denmark, Sweden, Austria, Belgium, Finland, Turkey, Poland, Russia, Greece, Switzerland, Netherlands, Norway, Portugal, Rest of Europe Asia Pacific: China, Japan, India, South Korea, Indonesia, Malaysia, Kazakhstan, Taiwan, Vietnam, Thailand, Philippines, Singapore, Australia, New Zealand, Rest of Asia Pacific South America: Brazil, Argentina, Colombia, Chile, Peru, Rest of South America Middle East & Africa: Saudi Arabia, UAE, Qatar, South Africa, Israel, Kuwait, Oman, North Africa, West Africa, Rest of MEA |
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
AI Datasets Market Strategic Shifts & Innovations
The market's focus is pivoting from the acquisition of raw data volume toward strategies that enhance data quality, efficiency, and relevance. This shift is driven by new technologies that automate curation and by enterprise demand for more dynamic, integrated data workflows.
Active Learning is a technique that uses machine learning models to intelligently select the most informative data points for manual annotation. Data science teams in technology and finance are adopting this method to reduce labeling costs and shorten model development timelines. This approach is decomposing the traditional, linear process of mass data collection into a more efficient, targeted cycle of curation and model refinement.
Regulations such as the Health Insurance Portability and Accountability Act (HIPAA) in the United States establish strict protocols for the de-identification of patient information. This forces healthcare AI developers to either invest in complex privacy-preserving infrastructure or rely on synthetic data for model training. The medical imaging segment is most affected, prompting vendors to develop auditable workflows to prove compliance when building diagnostic AI.
A significant demand-side shift involves enterprises moving from one-time purchases of static datasets to subscribing to API-driven data platforms. This model disrupts the legacy data brokerage channel, favoring providers who offer continuously updated and curated data streams for dynamic applications. This trend is most prominent within the financial services industry, where fraud detection and algorithmic trading models require access to near real-time information.
AI Datasets Market Segmentation
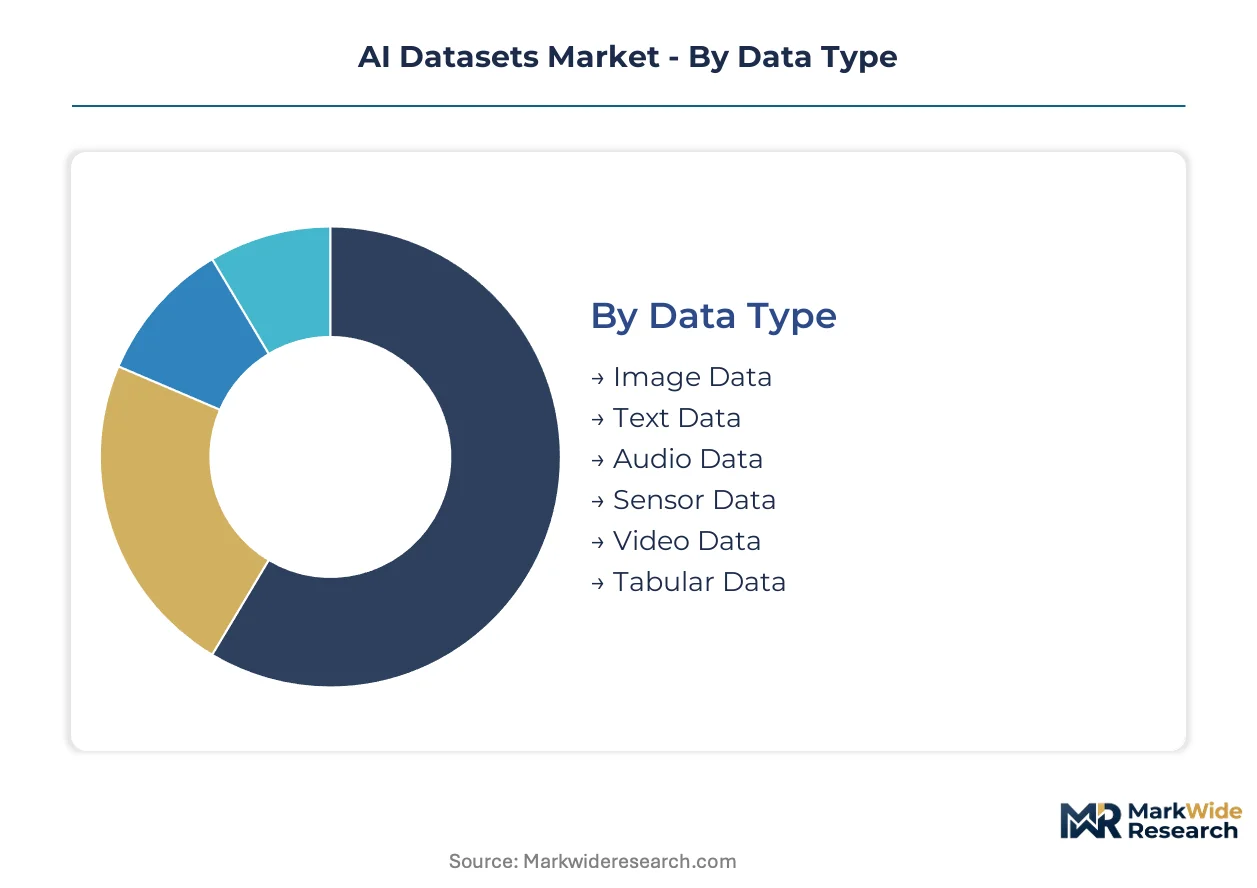
The AI Datasets market segmentation illuminates how diverse data forms and specialized applications drive value creation. This granular view helps stakeholders understand demand patterns across various industry verticals and deployment models. Analyzing these segments reveals specific opportunities for data providers and technology developers.
Data Type:
The Data Type segment experiences substitution pressure from synthetic data generation techniques, particularly for sensitive or hard-to-acquire real-world data.
- Image Data:High-resolution images, often with bounding boxes or semantic segmentation, provide visual context for machine learning. Demand concentrates in autonomous vehicle development, where camera imagery is critical for perception models.
- Text Data:Large corpuses of natural language, including articles, reviews, and conversations, are annotated for sentiment, entities, or intent. Generative AI expansion drives significant demand for pre-training Large Language Models.
- Audio Data:Speech recordings and environmental sounds are labeled for speech recognition and acoustic event detection.
- Sensor Data:Raw inputs from LiDAR, radar, and IMUs enable environmental understanding for autonomous systems.
- Video Data:Sequential image frames with temporal annotations support action recognition and behavioral analysis.
- Tabular Data:Structured datasets in rows and columns underpin predictive analytics and business intelligence applications.
Text Data retains volume leadership; Sensor Data holds the steepest expansion curve.
Industry Vertical:
The Industry Vertical segmentation highlights distinct application requirements, from fraud detection in finance to perception training in automotive.
- Finance:Transactional records and customer interaction data are annotated for risk assessment, fraud detection models, and algorithmic trading. Demand in the financial services industry requires continuously updated data streams for real-time applications.
- Automotive OEMs:High-fidelity image and sensor data, including LiDAR and radar, are crucial for training autonomous vehicle perception systems. Regulatory mandates like the EU AI Act compel these manufacturers to invest in high-quality, auditable datasets.
- Telecommunications:Network traffic data and customer interaction logs are labeled for service optimization and churn prediction.
- Retail Chains:Sales data, customer behavior, and inventory records support demand forecasting and personalized marketing.
- Agriculture:Satellite imagery and sensor data from farms are used for crop health monitoring and yield prediction.
- Manufacturing Plants:Operational data from machinery and production lines enable predictive maintenance and quality control.
Automotive OEMs drive substantial investment, while Agriculture shows promise for future growth.
Deployment Model:
Deployment Model choices reflect varying organizational priorities for data control, security, and scalability in AI dataset management.
- Public Cloud:Datasets are hosted and managed on third-party cloud infrastructure, offering high scalability and accessibility. This model supports rapid prototyping and large-scale data processing for numerous AI applications.
- Private Cloud:Data resides on dedicated infrastructure, providing enhanced security and customization for sensitive enterprise applications.
- Hybrid Deployment:A combination of public and private cloud resources allows organizations to balance flexibility with stringent data governance requirements. This approach is favored by enterprises needing to protect proprietary data while leveraging cloud elasticity.
- On-Premises:Datasets are stored and processed within an organization's own physical data centers, ensuring maximum control and compliance.
- Edge Deployment:Data processing occurs closer to the source, reducing latency for real-time AI applications like autonomous driving.
- Multi-Cloud:Utilizing multiple public cloud providers mitigates vendor lock-in and enhances resilience for data storage and processing.
Public Cloud offers scalability, but On-Premises deployment addresses stringent security needs.
Use Case:
The Use Case segmentation reveals how specialized datasets directly enable critical AI functionalities across diverse industrial and consumer applications.
- Natural Language Processing:Datasets of text and speech are annotated for tasks like sentiment analysis, machine translation, and chatbot development. Generative AI models for content creation and summarization significantly drive demand in this area.
- Predictive Maintenance:Sensor data from industrial equipment is used to anticipate failures and optimize maintenance schedules.
- Computer Vision:Labeled image and video datasets train models for object detection, facial recognition, and autonomous navigation. Autonomous vehicle development and medical imaging applications represent major demand sources.
- Fraud Detection:Transactional data and user behavior patterns are annotated to identify and prevent fraudulent activities in finance.
- Speech Recognition:Audio recordings with transcribed text enable AI systems to accurately convert spoken language into written text.
- Demand Forecasting:Historical sales data, economic indicators, and seasonal trends are used to predict future product or service demand.
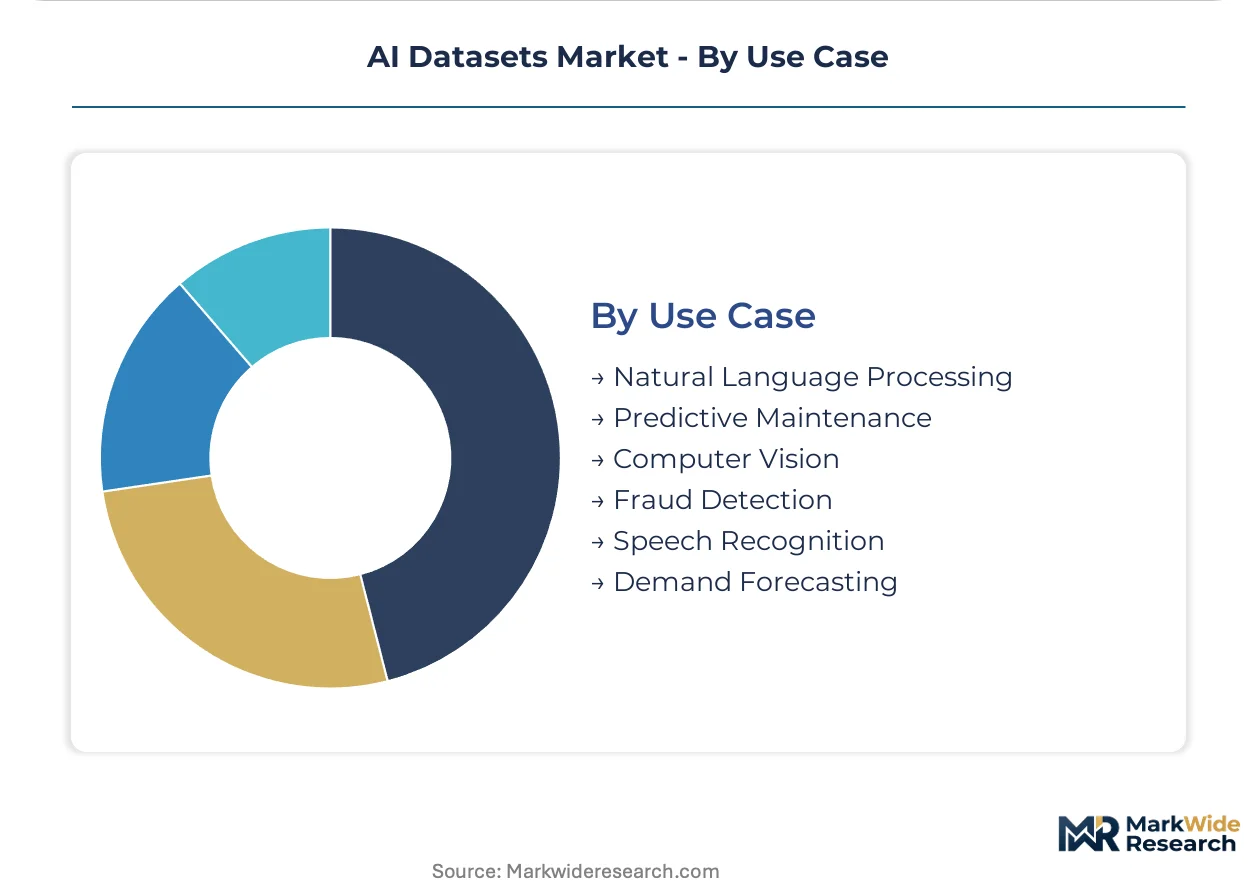
Computer Vision and Natural Language Processing remain core, with Fraud Detection gaining traction.
Need this report tailored to your region?
Request specific countries, segments, or companies — tailored to your requirements.
Regional Outlook
The AI Datasets market exhibits varying price sensitivities across regions. Highly regulated sectors like autonomous driving in developed economies demonstrate lower price elasticity for certified, auditable data. Conversely, general consumer AI applications in emerging markets often prioritize cost-effective, high-volume data solutions.
United States
Demand for specialized datasets in the United States stems from advanced AI research and autonomous vehicle development. HIPAA regulations heavily influence data sourcing and annotation for healthcare AI applications. Silicon Valley and Boston serve as key hubs for AI dataset innovation, fostering specialized annotation services.
Germany
Germany's automotive sector drives significant demand for high-fidelity sensor data for autonomous systems. The EU AI Act compels German manufacturers to invest in auditable, high-quality training datasets. Munich and Stuttgart feature concentrated automotive OEM research, requiring precise image and LiDAR data.
China
China's expansive digital economy fuels massive demand for text and image data, particularly for large language models and computer vision. Government initiatives like the "New Generation Artificial Intelligence Development Plan" support domestic AI data infrastructure. Major technology centers in Beijing and Shenzhen are rapidly expanding AI dataset collection and annotation capabilities.
India
India's burgeoning IT services sector and focus on localized AI applications generate demand for diverse language datasets. The country's national data governance policies are evolving to balance innovation with privacy. Bangalore and Hyderabad are emerging as centers for AI data labeling and annotation services, leveraging a large workforce.
Japan
Japanese industries, including robotics and advanced manufacturing, require high-precision datasets for automation and quality control. METI promotes AI development through various programs, influencing data acquisition standards. Tokyo and Nagoya are critical areas for AI dataset development, particularly for industrial automation and automotive applications.
AI Datasets Market Key Industry Players
A small set of integrated leaders sits above a broader specialist tier within the AI Datasets market. This market structure features a few large platforms offering end-to-end data solutions alongside numerous niche providers focusing on specific data types or annotation tasks. Strategic archetypes include full-service data providers, specialized annotation service firms, and data lakehouse integrators. Market participants are increasingly pursuing strategic partnerships to expand their service portfolios and geographic reach.
Within the full-service data provider archetype, Scale AI and Appen exemplify companies offering extensive annotation capabilities and managed services. Scale AI focuses on complex computer vision tasks for autonomous systems, providing sophisticated tooling for demanding applications. Appen, conversely, leverages its extensive global crowd-based workforce for large-scale data labeling projects, particularly in consumer technology. Databricks occupies a distinct position as a data lakehouse integrator, supporting enterprise data science teams with integrated AI model development workflows and MLOps capabilities.
| Leading Market Players |
|---|
| TELUS International |
| Databricks |
| Scale AI |
| Snorkel AI |
| Labelbox |
| Appen |
| Cogito Tech |
| SuperAnnotate |
| iMerit |
| Others |
Cost & Logistics Intelligence
Massive economies of scale in data annotation and processing drive significant supply concentration, which in turn influences price floors for standardized AI datasets. This market structure allows large providers to offer competitive pricing on high-volume, generic data, while specialized, high-quality data commands a premium.
Pricing Analysis
Ongoing API subscriptions and continuous data stream services drive lifetime value within the AI Datasets market. Pricing stratifies across premium, standard, and economy tiers based on data quality certification and customization level for specific AI models. Pricing pressure stems from the increasing availability of open-source datasets and advancements in synthetic data generation. Enterprise clients in highly regulated sectors like automotive OEMs demonstrate the least price sensitivity for auditable, compliant datasets, while smaller startups prioritize cost-effective, high-volume options.
Supply Chain Analysis
The complexity and cost of managing distributed human-in-the-loop annotation services globally represent a significant inbound logistics challenge. Geographic supply concentration for annotation expertise centers in countries such as India, the Philippines, and parts of Eastern Europe. The market depends on raw inputs including diverse image, text, audio, and sensor data, alongside specialized annotation software tools. Data privacy regulations across multiple jurisdictions create a structural risk for data sourcing and processing. Distribution primarily occurs through API-driven data platforms and secure cloud-based transfers for custom projects.
Get the full picture before you read further.
Download a free sample with table of contents, companies, segments, and methodology.
Analyst Recommendations
The AI Datasets market faces a critical scarcity of highly specialized domain expertise required for complex data annotation tasks. This gap creates bottlenecks for advanced AI development across critical industries.
For Market Incumbents:
Shield core market share by investing heavily in proprietary synthetic data generation capabilities to overcome privacy constraints and fill data gaps. Acquire niche data governance technology firms to enhance auditable compliance with frameworks like the EU AI Act. Continuous R&D into active learning algorithms will reduce annotation costs. This strategy counters the threat posed by rapidly evolving open-source AI models and increasing regulatory fines.
For New Entrants and Emerging Players:
Anchor in underserved regional markets by developing context-specific datasets for local languages and environments, particularly in technology hubs across India and Brazil. Target specialized segments like agricultural AI or medical imaging, where domain expertise is scarce and data quality is paramount. An effective go-to-market angle involves offering API-driven data platforms with flexible subscription models, catering to the specific needs of small to medium-sized enterprises.
For Investors and Strategic Acquirers:
Niche data provenance and quality assurance technology firms represent attractive acquisition targets for long-term growth over the next decade. These companies offer critical solutions for regulatory compliance and model robustness. The signal to watch is an increase in M&A activity focused on companies providing auditable data pipelines and specialized annotation tools for high-risk AI applications, indicating a market consolidation around quality and trust.
| Strategic Initiative | Industry Significance |
|---|---|
| Invest in Synthetic Data Generation | Bypasses privacy constraints and generates data for rare scenarios, enhancing model robustness. |
| Acquire Niche Annotation Specialists | Secures scarce domain expertise for complex tasks like medical imaging and autonomous systems. |
| Develop Localized Data Platforms | Addresses specific language and environmental needs in emerging markets, driving regional AI adoption. |
| Enhance Data Provenance Services | Meets stringent regulatory demands for auditable data sourcing and consent, building trust. |
| Integrate Active Learning Workflows | Reduces manual labeling costs and accelerates model development cycles for enterprise clients. |
Research Approach
Two parallel data streams informed the analysis: extensive primary interviews with industry stakeholders and rigorous secondary validation. We engaged AI research scientists, automotive OEM data leads, data annotation platform CTOs, and regulatory compliance officers. Secondary sources included government AI policy documents, academic research papers, technology patent databases, and venture capital funding reports. This approach facilitated bottom-up and top-down triangulation of market data.
The analytical framework projected market dynamics across the analysis window, modeling segmentation dimensions including data type, industry vertical, deployment model, use case, and regional regulatory frameworks. Compound Annual Growth Rates were derived from historical trends, coupled with future demand projections for autonomous vehicle production forecasts and Large Language Model development roadmaps. This comprehensive approach ensured a robust quantitative market outlook.
Material uncertainties — such as unforeseen geopolitical shifts or rapid AI regulatory changes — sit outside the modeled envelope. Forecasts reflect assumptions regarding technological advancements and market adoption rates. Outcomes outside this envelope would require model recalibration.
Need Custom Data?
Can't find what you're looking for? Our analysts can build a custom report tailored to your exact requirements.
1,000+
Global Clients
150+
Countries Covered
65,000+
Reports Available
Frequently Asked Questions
Why Work With MWR
Trusted by 1,000+ businesses across 150+ countries for high-stakes market decisions.
Ready to access intelligence that moves business?
Browse Reports →Trusted by Global Leaders
From Fortune-level organizations to global SMEs, we provide intelligence for high-stakes decisions.
Multi-Language Support
Research available in French, German, Spanish, Chinese, and more.
ISO & IAF Certified
Globally aligned quality standards ensuring methodological discipline and data integrity.
Competitive Relevance
Free inclusion of 3–4 additional companies of your choice in every report.
Customized Insights
Tailored intelligence for market entry, niche expansion, or competitive benchmarking.
Post-Sale Assistance
Dedicated coordination to help interpret findings and address queries post-delivery.
Cutting-Edge Methods
Structured data collection, advanced analytics, and expert validation for reliable forecasts.
Value for Investment
Credible, structured intelligence at a cost that makes strategic sense.
What Our Clients Say
My team needed the real numbers on AI spending for our Reinvention Services work. MarkWide delivered. No fluff, just a clear look at where the money is actually going. It saved us about three weeks of guesswork.
Accenture
We recently leaned on MarkWide Research for a deep dive into the evolving snacking habits within Southeast Asia. Their report on the premium biscuit segment was exceptionally detailed, providing us with the specific consumer sentiment data we needed to refine our regional flavor strategy. It wasn't just a data dump; the cultural nuances they captured helped us avoid several localization pitfalls.
Mondelez
Director of Global Consumer Insights
For a recent engagement in the automotive sector, we needed rigorous, independent verification of EV battery recycling capacities. MWR delivered a report that made our work easier. Their ability to segment the competitive landscape by chemical composition and regional throughput was exactly the kind of 'hard-to-find' intel that our team was looking for.
BCG
We were looking for a report on Xcelerator ecosystem's potential and got in touch with MarkWide's team through one of my old colleagues who worked with them in the past. Their research team was incredibly polite and were always available for us which was important for my team as this was a custom project. Their methodology for tracking industrial IoT adoption gave our R&D heads the clarity needed to prioritize our next-gen sensor development.
Siemens
Head of Industrial Digitalization
During a recent M&A project, we needed a fast, reliable breakdown of the Fintech landscape in Southeast Asia. MarkWide came through with a report that was actually readable and focused on the metrics that matter. It saved my team a good week of primary research, which, given our timelines, was a massive win.
KPMG
Advisory Partner
We tapped MarkWide Research for a deep dive into the ESG reporting software market. At Deloitte, our clients expect us to have the most current insights, and this report didn't disappoint. It provided a breakdown of the competitive field that was far more detailed than what we were expecting.
Deloitte
Lead Consultant, Sustainability Services
For our semiconductor division at Samsung, the supply chain forecast from MarkWide was incredibly useful. It provided a realistic outlook on raw material availability that helped us refine our production timelines. No fluff, just the data we needed to make a tough call.
Samsung
The value for our organization comes from three things: depth of research, specificity of segments and being easy to work with. As important as the first two are, the third can't be underestimated. MarkWide Research, maybe more than any other research vendor, wants to know what is top of mind for our team and what big questions we are grappling to answer. Their customer first approach and high value engagement model have given us great analysis and excellent value for money.
3M
I can share that it was a positive experience wherein MarkWide Research demonstrated flexibility to adapt to our needs and delivered an excellent report that fits all our requirements. Personally, I liked the timely follow up by the team and we will definitively reach out in case more research support is required.
VITO
Related Reports
Artificial Intelligence (AI)
Asia-Pacific Generative AI Market
Artificial Intelligence (AI)
US Voice Recognition Market
Artificial Intelligence (AI)
Supermarket AI-Powered Checkout Market
Artificial Intelligence (AI)
Edge AI Market
Artificial Intelligence (AI)
Text-To-Speech (TTS) Market
Artificial Intelligence (AI)
Explainable AI Market
Artificial Intelligence (AI)
Artificial Intelligence Oven Market
Artificial Intelligence (AI)
Intelligent Virtual Assistant Market
Artificial Intelligence (AI)
Artificial Intelligence in Supply Chain Management Market
Artificial Intelligence (AI)
Europe Synthetic Data Generation Market
Artificial Intelligence (AI)
Asia-Pacific Natural Language Processing in BFSI Market
Artificial Intelligence (AI)
Artificial Intelligence Chatbots Market
Artificial Intelligence (AI)
Industrial Artificial Intelligence [AI] Market
Artificial Intelligence (AI)
No-Code AI Platform Market
Artificial Intelligence (AI)
Latin America Artificial Intelligence Market
Artificial Intelligence (AI)
Smart Virtual Personal Assistants Market